Enjoying this issue?
Get tomorrow's AI & engineering digest in your inbox — hand-picked, summarized, and always spam-free.
No summary yet. Click “Regenerate summary” to queue one.
Stop scrolling. Start reading smarter.
Receive the day's most important AI & engineering updates in one concise email. No spam.
Transcript (captions)
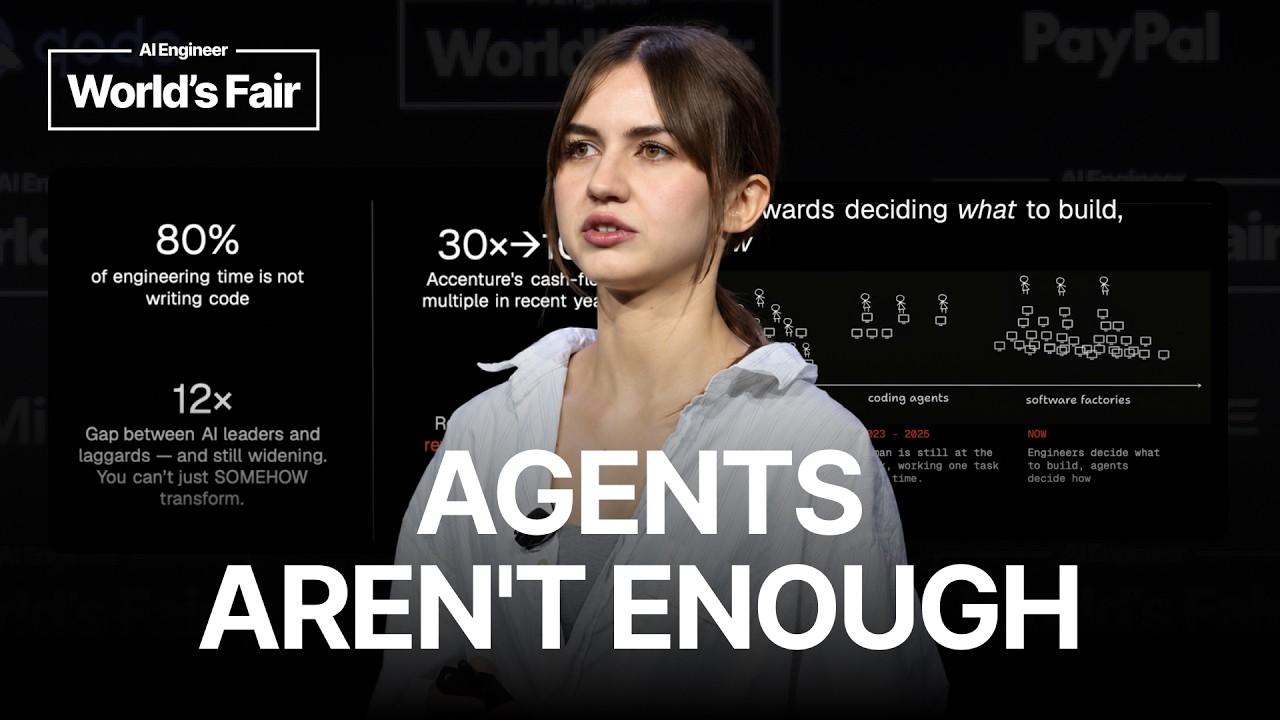
Uh hi everyone. Hey what's up? I'm Teresa. Uh and today I will be talking about software factory. uh everyone is talking about software factory but only few people are actually building one and
even fewer people know what it actually takes to build one and how to define it. So I will be talking about what is a software factory, should I build your own or outsource it, what works in
production already, what are the main challenges and how much is this all going to cost? Uh my name is Theresa. I work at a company called factory.com and we've
been building uh this concept of the software factory for quite a long time but finally uh the technology is catching up and it's possible to build this in production for enterprises like
EY or Adobe uh I would define the software factory as the whole loop the whole life cycle of developing software with autonomy which doesn't mean just coding and generating code by that I
mean collecting all the signals reacting to user feedback to logs, prioritizing what's important, then orchestrating it all, executing, validating, doing really good uh testing in production and then
iterating on all this uh while also continuously improving in the process and gaining new knowledge and new skills. So this is just our dashboard how our software factory looks if you if
you look at it and it's catching the whole cycle there. uh this is just some history and by history I mean 2023 in AI. So the software factory wasn't really possible before even though we
always had this idea from the beginning of uh CH GPT lounge and others we had this idea of the continuous loop there was autog baby agi already with the concepts of iterating on the software
but it didn't work before because the LMS were hallucinating there was problem with context length uh problem with the reasoning quality uh different problems like this or we were missing good
environments where the agents can actually work in the isolation. So all this kind of led to why the software factory is the paradigm that's starting to be popular now and actually useful.
I like to define things by what they are not. So I want to say software factory is not just coding agent and it's not even a swarm of coding agents even thousands of agents because generating
code writing code that's the easy part compared to all the others. uh engineers don't even spend most of the time uh just writing code. The challenges are the rest of it. Uh so this is what I
want to enhance and it's also not just some consultancy or just some abstract strategy that someone will try to sell you and to your organization. Uh I think the approaches are of course different
but we believe you should really rebuild your organization from ground up to be ready to become a software factory like you can't invite a consultancy and just throw something in the middle of your
organization. You should really be mindful and rebuild it from scratch. uh this is the approach I like uh showing to building the software factory and I think it's similar to building the
real team of humans because there is a lot of agents as I said they will be testing validating iterating and it all can end up as a big chaos uh so you need to be mindful and I would say the three
important things is being agnostic in the software factory so being independent of LLM choices uh of how you already work as the organization then you need to be autonomous. So you need
to give the agents the right trusts and all this permissions and governance and you need to trust it to run really for a long time because the predictions are that agents will run even a year or more
years without the human in the loop. Of course that sounds ambitious but for example our missions already our long runninging sessions already build uh things and run for weeks. So it's not
that crazy. And third thing always improving. So same as human organization you need to onboard any new people in your team by giving them good uh code base understanding good structure
documentation and also let them improve in the process and gain new knowledge and share it share it within the team. So these are the three points and now let's talk about the agnostic one. Uh I
think the important thing to point out if you are a builder and building different primitives of the software factory you need to be ready for how everyone is already working you need to
work across environments like Slack, GitHub and connected to everything and you need to also allow people to already bring subscriptions they are using because there is every every time there
is like new technology, new frontier models, uh new benchmarks and it's so difficult to catch up but also to predict what we'll be winning. So it's best to be agnostic for everyone.
Uh then there's the topic of being agnostic to models. Uh this is a topic of a lot of discussions recently and this chart is from this chart is from CEO of Coinbase uh who tweeted about how
they started uh started saving money in their organ or organization on AI but without reducing the token spend. So the black line is how much they spent on tokens. They continue growing and token
maxing but they stopped spending so much money. Uh how they did it uh different tricks like different default default models for people. So stop pushing people to use only the frontier as a
default. Then caching of course uh to stop preferring the stuff every time. And then no limits on spending but just needing to see the results if you spend a lot. And the last thing that's really
important topic is routing. So smart routing between LLMs and just a token optimizing between uh the LMS instead of just spending so much tokens. Uh we built uh a thing in factory called
uh automatic model routing and there's been a lot of questions around it but what it does is it automatically routes between different models in your process. The important thing is it
decides first what model is most optimal and then uh it can switch to different model if it's failing the task or in case of any troubles but it usually doesn't happen and important thing is it
doesn't just help uh spend money. It also helps with reliability or with speed because open source models are often faster and uh if one LM provider fails you can just switch to another one
automatically. So it really does more things than just saving the money. This uh is our benchmark which is very conservative. I prefer conservative benchmarks but I think the direction is
clear. You can save for example 25% but even more probably. Uh how the routing works uh there are four parts. First you just assign the task and you don't really need to do
anything but as an organization you can for example give different permissions and different default models to different people which is very useful like marketing or sales or engineers can
both uh have different default models and then you have the classification which is the important part. This is the magic of the routing. You need to really uh look at the structure of the prompt
of the uh code base of how difficult the task is, what tools are being used, all these factors and make a classification of difficulty of the task. Uh after that you basically do a threshold of what is
enough to accomplish the task and you choose the cheapest model above the threshold. So cheapest model that is predicted to accomplish your task and then you go.
Okay. So when we launched this we got a lot of questions like does it actually work? What if uh the model mis routes? Uh is it slower? Is it more expensive actually? What if the model can't
accomplish the task or what if it needs to upgrade? And how do you handle caching? So I think these are all valid questions and that's why it's so difficult to build a good router like
you need to basically classify it very well and the challenge is to not not to need to switch too often but even if you're switching in the middle of the task to difficult to more difficult
model you still overall are faster probably because it's still worth uh this is just some overview of caching uh lot of questions we got on this was also So how do we handle caching? Do we
do discounts for users? Uh because LLM LLM labs of course save a lot of money by caching and skipping all the context prefill all the time. Uh open models can do this as well. I think people
sometimes forget this and you can just host open models as well uh on dedicated compute and you can take the same advantage of the caching. Uh so I want to enhance uh the final price for users.
is just a pricing decision. It's not a technical challenge because everyone can do caching. It's just what price you pass on the users and what deals you make with the API providers.
So this is uh being agnostic and now the autonomy which is the core of the software factory. Uh everyone is talking about loops. Uh loops I think have been here the whole time already in different
context. They are just now leveling up and moving to the context of agents. You probably heard about the Ralph loop and specifying the tasks and splitting to subtasks for agents. Uh this is a known
concept and uh the question is not the loop itself but the question is how how you define what it means to be done in the loop. This is one example from my colleague uh he he made a loop uh of
agents building 3D printing of our logo. uh I think here you can see what is the challenge of the loops because uh before in programming loops had clear criteria of what it means to be done while now
the criteria become open-ended because a lot of the tasks are very nondeterministic it's basically open world you can do even real stuff like printing something and it's really
difficult to define how do you verify that the loop was done that the task was accomplished so that's the difficult part uh yeah they just need to be verifiable
This I call the scary chart. It basically shows that the tasks and how long they run autonomously with agents have been increasing. But still it's not that reliable. Even if you can run for a
very long time, it doesn't mean that it will be reliable in production and you still probably need to need to iterate on it and uh provide feedback. So it's still not solved and there are problems
like cheating. For example, if you write the what it means to be done in the wrong way, the agent can try to pass your tests but not really like not really verify what you need to do and
accomplish but instead try to solve just passing your test. So cheating by that uh we have something called factory missions and this is like long longunning sessions of the agents. We
just call it missions because we send the agent to the mission and uh the missions work in the loop and iterating on task until it's done and they can do it even for weeks and uh the main agent
is orchestrator and then it's uh assigns work to workers agents and then validators who review the task. So this is one example uh real mission from our customers that run 16 hours and just
just to see how important is the validation as well. it takes even 40% of the whole process. Uh to summarize, the orchestrator just decides and writes the conditions what it needs to be done.
Then it gives it to the agents called workers. The agents work on it. And what is interesting or worth noting is that they work in a sequence. So they don't work in a swarm or parallel. The agents
work in sequence and everyone accomplishes something and passes it to the next one. uh we actually found that if you do this you end up with more fresh context and
kind of fresh head. Same with when with humans have like other colleagues verifying their code. So similar thing we just let the agents pass to the next one. But still every worker of the
sequence can have parallel agents doing smaller tasks. So I don't know researching on the web or building files during that. So they are in sequence and everyone has sub agents as well. and
validators they review the output and provide feedback and send it back to the beginning. Uh important thing is uh the validators judge code that they didn't write. Uh
there's something from the orchestrator agent called validation contract uh that's written before any code is done. And first type is scrutiny validator. Second is user testing validator. The
scrutiny is the one who really verifies how the codebase looks. the liners types tests it's really rigorous check of the code but the second I think is really interesting is user testing validator
and that's the one who is really in the arena trying the things so it doesn't care how it was made it just goes it works in its virtual computer and it clicks on the stuff and really checks if
everything works I've seen one engineer migrating uh code bases with droid with our agent and uh it really needed the agent in the end to click through the stuff because with other products it
just created created the product but it didn't work and was wasn't interactive. It was just a dummy result. So our agent that really clicked on the stuff uh allowed to check that it's actually
working and not just looking good in the code. I think this is one cool thing that was also allowed by the progress in computer use and the persistent environments virtual machines for agents
which also wasn't here before or wasn't that great but now it's really great so it's allowing to go in the arena as an agent. Uh this is just one example of real mission from our users. I I like to
just learn what users are building and get feedback and this is just uh how it can look in your dashboard. And this is how I visualize the missions. What is interesting is that it's just a loop
with smaller loops because every of the agents are running in loops as well, but overall it's like one big loop. Okay, maybe this is a bit weird, but I just like that it's all loops with smaller
loops. Uh, okay. And the third part, always improving, always learning. Uh there is this elephant in the room context with agents. A lot of questions
which are valid are like how do you navigate the context blo because you work on these long missions in the software factory and how do you actually keep the context clean and that's very
valid because enterprises especially they use hundreds tools they use Figma, notion, Gmail, drive, slack like hundreds tools on average. So all these have specification in the code. all
these have schema and parameters and log descriptions. So, uh it can cause agent to really bloat with that and pick wrong tools if there are two tools that sound similar or to actually lose context
because they fill up the the context window and need to compress. So, this is really dangerous. Uh for this we have something within the software factory called uh deferred context engine and we
build it such that we just progressively disclose what's in the context and what tools to use. So we basically have a surprise tools uh that help later only if they are actually needed. So it first
just has short list of the tools and uh only a short descriptions and when it's needed actually in the code uh they can call the tool and fully load it. So important thing is nothing is actually
removed it's just hidden and not reachable until needed. So it's just for later and important thing is it actually saves a lot of tokens uh at scale once you use more and more tools. uh the more
actually you save it really scales and you can save 50% of tokens or more. Okay. Uh another thing which is tricky and was surprising for me for the first time is that when adopting AI you either
succeed big or you can fail big the same way it's a bit of power law. So if your codebase is not ready, if you don't have structured codebase and all important things, then adopting or turning into
software factory can actually make you end up worse and make your code degrading. And uh there is a big and growing gap in productivity between those who just adopted AI versus those
who actually thought about it a bit more. Uh there is another data from Stanford about yeah without structured uh code base and being ready and documenting
well the AI can make your code worse and I think if you are engineers you probably can agree that sometimes AI really makes a mess and this can really compound more and more and it's
difficult to go back. uh we have something as a part of the software factory uh we have something called agent readiness and it's a framework I don't like the word
framework but uh take it as a hygiene check of your codebase and things you should do because there is actually nice correlation between how your codebase is looking and all the details there and
how good you're going to adopt the AI and end up productive instead of uh with a messy code base. So there are things like how how reproducible is your developer environment or if you have
written good tests if you have all things well documented what's the style of your code all the tests and llinters uh everything that you would do also to keep codebased screen. So these factors
actually show to be very useful and we have our bigger customers actually go through this agent readiness framework and do all checks and then they can follow up with recommended actions uh
how to fix that. Uh I think one more thing about the context and the continuous learning in the software factory is the most of the time when working with AI or at least
from my experience is that you keep repeating to agents how how do you want the things done and you feel like the agent doesn't really get you and I think this is again nice parallel with human
organizations and teams because when you join a new company there are a lot of rules that are not really codified anywhere like you just learn and observe how things are done and there are a lot
of things between the lines that you can't really learn anywhere else than just observing. I think this is big challenge for agents as well and one thing we launched for that is plugins
which are like packaged reusable skills and context and the things behind the scenes that you can really codify or auto which is automatically updating our documentations and uh yeah and um
reviewing and documenting what you have. So the question is what will happen to us humans if we build software factory like this? Uh will humans just lose jobs and go to permanent underclass? I think
they will not. And uh I want to be positive. So I'm thinking of this parallel of humans just moving up uh levels up to the uh to the cooler tasks than before. I think we actually had
before the same same experience of us as humans abstracting some levels up and we actually started ourselves as human computers. We actually were the computers doing all the most detailed
stuff at the beginning. Then we had programming languages codifying some of it, abstracting and then coding agents. So outsourcing some of it but uh still being in the loop very closely uh and
very monitoring everything. And now we are moving kind of up to software factories where we manage these agents as I said orchestrator agents and workers and validators and all these
teams structured teams of agents that work really continuously in the loop and we just monitor and decide what to build. Uh so I want to really end this positively. We should be as humans
deciding what to build in the software not how to build it. uh because that's up for the agents and by this uh continuous cycle of autonomous software I think we can actually achieve that. Uh
this is one warning chart or if someone thinks AI will take the cool cool stuff from us. I believe actually it will take the annoying stuff and in enterprises and organizations you already spend a
lot on alignments on the meetings as I mentioned basically the thing behind between the lines that you really need you need to get context from everyone share your status sync on the things on
meetings so all these things could be actually outsourced to your software factory and you could be just talking about the cool stuff okay so this is it thank you so much go touch some grass
and let your agents uh built for you. Thank you.