Enjoying this issue?
Get tomorrow's AI & engineering digest in your inbox — hand-picked, summarized, and always spam-free.
TLDR
An entity resolution job on Ohio campaign finance records that was projected to cost about $10,000 was completed for under $800 after a newly launched cheap model was dropped into a Southbridge pipeline, with all 23,317 cases ending up with verified labels. Olickel's argument is that this is what cheap intelligence actually changes: transformation is no longer the expensive bottleneck, so there never was a universal schema, and schemas only come together at decision time as just-in-time ontologies. The concrete takeaway is that letting fast, cheap models self-optimize against a defined failure surface beats building for a schema you will never fully know.
Key points
An agent ran for 10 days, made over 4,000 harness runs and 90,000 model calls across roughly 6 billion tokens.
Jev and Luna agreed on 194 of 200 held-out families; all errors were in the six disagreements.
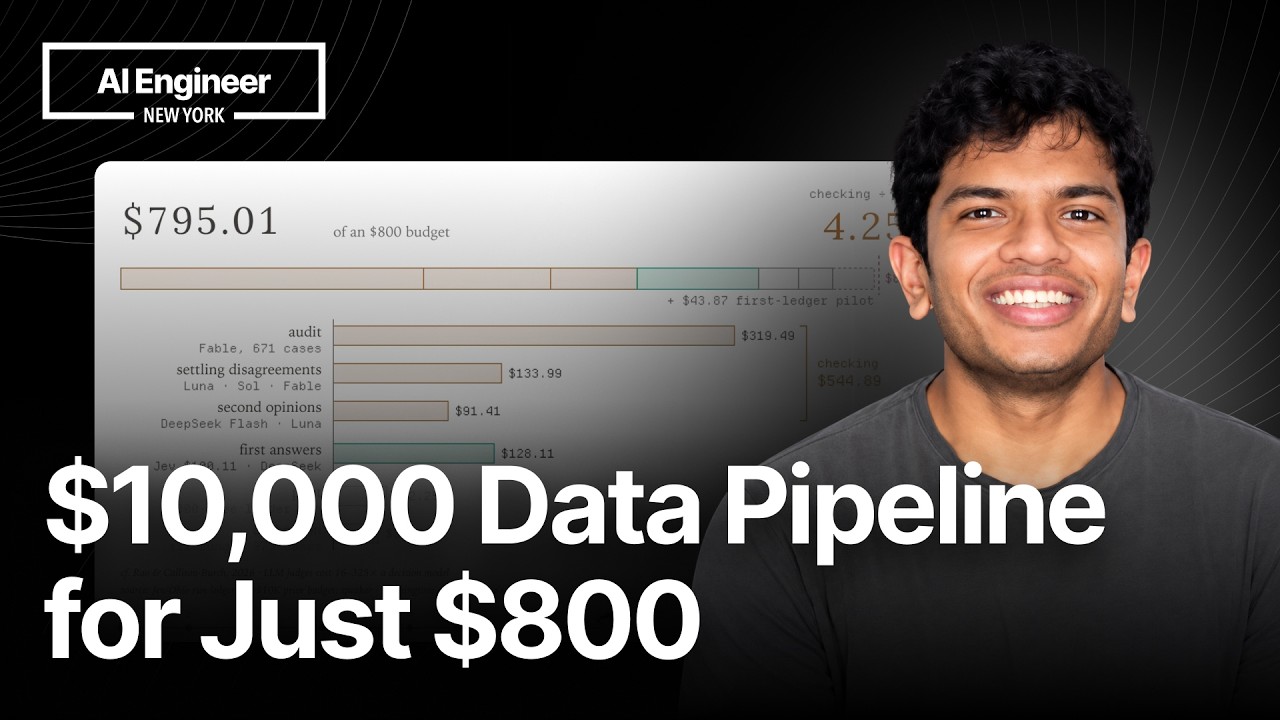
Checking answers cost about four times as much as producing them: $545 versus $128.
Model priors caused silent data errors, including turning $784,000 into $5.3 million of debt.
Four missing capabilities block native self-optimization: stable deployment, bounded experiments, methodology, and a failure surface.
Tools mentioned
Techniques
- Just-in-time ontology: merge record context with decision context at the moment the decision is known
- Burrito surfing: iteratively swap models for cheaper or faster options and compare against known intermediates to tighten success criteria
- Cross-model prior intersection: use disagreement between models from different families to surface errors
- Checking layer architecture: have a cheap model answer first and a reasoning model verify anything uncertain
- Codons and rigs: run validation code between bounded work segments that can be reused, looped, and sequenced
Stop scrolling. Start reading smarter.
Receive the day's most important AI & engineering updates in one concise email. No spam.
Transcript (captions)
[music] So, I really love this article from Hannis at DuckDB where he asks if we lost a decade chasing distributed architectures that presumed compute and
storage were slow and expensive. Capability in every era though defines architecture and tooling and the tooling lags behind consistently. We first made compute cheaper than storage and then we
gave it to everybody and then we made it faster and every single time architectures undergo this massive change. All of our data infrastructure today is built on the idea that
transformation is expensive. What if that wasn't true anymore? I believe we've solved the final bottleneck in transformation, general intelligence or judgment, and we've made
it accessible on tap all along the burrito frontier, which puts us right on the verge of a paradigm shift. So, in this talk, we're going to cover why single ontologies always fail, the three
roles models play in pipelines, intersecting model prior for better results, and burrito surfing. how today's models can tune a workload for cost, speed, and accuracy all at the
same time. Here's a quick example. When Jeff launched, we already had an entity resolution pipeline running, working out Ohio's campaign finance records and whether they belong to the same person,
company, or committee. It was projected to cost about $10,000. Our systems took that new model, worked out where it fit, tested over a dozen approaches, and integrated it. 10 days
after that first call, we had final ground truth for every donor case in Ohio under $800. That is the power of burrito surfing and just in time transformations. So, let's get into it.
Ontologies are the enterprise version of mind maps. It's this tarpet that sucks us all in, including me. I talked about a single universal schema when I founded Southbridge two years ago. The popular
conception and it's not wrong, it's just small part of the picture is that migrations and ontologies fail because of a lack of buyin. That they're abandoned halfway through that
organizations and people never switch over. All of that is true 100%. But buyin isn't the primary reason. See, if you could integrate and migrate all of your information into a single super
schema in the blink of an eye, you still have to content with the truth that there is no super schema. There actually are four schemas. The first one belongs to the source. Wherever the information
comes from, let's take temperature as an example. Say I ask you to write down the temperature. The source schema is whatever you have access to. your phone gives you your regions, temperature,
sensor on your desk which is less accurate but it's more local or your watch but even your patience in following through on my request as part of that source schema. The second one is
the storage schema. There's only so much you can write down. You can't write down the firmware of the device you're using. You can't even write the time down to the second
because you couldn't finish writing all of that inside of a second. This is the schema imposed on you by storage. The third one belongs to the decision. Why do I need you to write the temperature
down? Maybe I'm figuring out what makes you comfortable, in which case I need temperatures from you spread throughout the day, and I need to make sure that it's you that's doing the measuring.
Maybe I'm building weather migration maps, in which case I don't care who does the measuring, but I care a lot about your exact location, the time, the device you used, and whether that's
changed. or maybe I'm deciding whether to install sensitive equipment and wear and you yourself become this variable that I need to cancel out. There's a fourth one though which we'll get to
when we talk about prior. It's this recent issue. The true problem is that you will never know all four schemas at the same time except at the moment that the decision is being made. In almost
every enterprise and every home most of the data being recorded has little idea what it's going to be used for. Take a customer, the first box in every ontology. To billing, a customer is
whoever pays. To support, it's whoever calls. To compliance, it's whoever we're on the hook for. And the only time you know is when the decision is known. Should we refund this order? Can we
extend this account more credit? Suddenly, what you need to know how and to what degree becomes extremely clear. This is why I was wrong. There is no universal schema. There is no concept of
a customer that's divorced from the question that you want to answer. And pulling these schemas together is the process of transformation of making information actually useful. Taking the
context that it was recorded in and merging it with the context of the decision and that takes discernment. Doing that merge when the decision space is known instead of ahead of time is
what I mean by a just in time ontology. So we'll come back to discernment with a story from my last job where like most of my job was to make sure that certain numbers just did not exist ever
before that a little bit about me and us. We are best described as obsessives. Obsessives who embed intelligence into pipelines. Pipelines that can scale, that can run over and over again to take
work truly off our hands. and pipelines that can mature in cost, performance and speed all on their own. And most of the work we do in data breaks into three regimes. The first is write ones run
once. If you do any kind of development, think of these as monster scale immediately invoked functions. They're built for something single use like joining a data set, mining information,
or answering one specific question and then they get torn down. The second is write many run once where lots of smaller and larger workloads are built for one large common goal. The closest
thing you might know is like large migrations, years of records, moved out of systems nobody fully remembers. Lots of workloads built for one move and verified individually at source checked
against the others because all of it only happens once. The third though and this is bread and butter is the most common is write many run. These are repeatable pipelines that are built and
maintained over time as we add more information in. And at Sautri, we've moved so much work off the main thread and into these repeatable systems from benchmark design, tracking, coding to
making subtitles for movies that we want to watch. Almost everything we do in the modern world is a transformation of data or it's bottlenecked by how hard it is to transform data. And in all of these
cases, our job is simple. Make sure people can rely on the results. In just two years, we've gone from figuring out how to make early 3.5 turbo level models reliable on things like healthcare,
aging, mining research to building Hankwave or open-source harness for data work and then using that to get models to work together at terabyte scale. Today we have systems that can
self-optimize. You give them the problem, a way to fail safely, a place to work, and they find the shape of the solution. They pick the right models. They run the pilots. They scale up and
they burrito surf their way to the best option they can find. So story time at my last job, the question we heard most often was, can we make this decision data? And sometimes
that was the right question when we had thousands of vessels on the platform. The problem is that we also asked it when we only had 50 users. And if you know statistics, you can explain really
well why AB testing 50 users is a bad idea. Not because you're not going to get a result, but because you will. So the only real option was to do not produce a number at all because the
moment a number exists, it argues for a result. Today though, it is worse. Interactive agents will always give you an answer. They'll give it to you quickly. You ask for a transformation,
whatever, and you get a contra yes sir. What this means is mistakes add up quickly. Moment in chat can be a prod nightmare forever just waiting to be discovered. The primary reason that this
happens is that intelligence as it relates to data work today occupies three separate roles that coding agents kind of mash into one context window. Let's pull those apart because it'll
help a lot when we get to decision models because they fit into exactly one of these three. The first one is building and designing the pipeline which is breaking down the problem
writing the early specs authorizing spent. The second one and this is usually confused with the first and given to the same models is working inside the pipeline actually doing the
work reading the PDF writing to databases checking results. Before we get to the third one I want to make it clear that these two roles pull in very different directions. The first one
wants slower models with heavier, thicker tokens, models that can think more, walk around a problem and see the angles, digest documentation, understand how these pipelines get built, and
predict how something will do before it even starts, right? Opus or up. The models you want inside pipelines though are the opposite. You want them cheaper, faster, specialized, good at following
instructions, repeatable workers with noable defects. You see the same thing in nature. A leaf cutter ant colony for example runs on four different sizes of worker right small medium high X high as
you watch any system that you design review or hear about listen for what slots and where in this layer cake it makes a big difference because we had this distinction bringing in Jeff in
this newly exploding class of decision models was very easy because they're workers built they're built for quick contact with information and they're deployed at the bottom end of large
workloads So third category though, this is something we call the hill climbers or surfers models that can take a first run and self optimize. Given the right
knowledge, instructions and an incredibly stable surface to stand on, they can try new things, vary budgets to limit cost exposure, debug quickly, take notes, surf their way not just to the
right solution, but the optimal one. We call that burrito surfing, and we'll cover it at the end. But first, let's talk about our experience with Jev. Jev launched on a Tuesday when we were deep
into an entity resolution pipeline. You were working on donors in Ohio's campaign finance. And at this point, a lot of people have seen this chart. We talked about the results before and
adapted some of the ongoing work to the data set. So, you can download it for yourself prompts and everything. What we didn't talk about is everything behind that one arrow. And what happened when
we ran the same idea on the whole state? Here are all of the architectures we tried. We started with three designs on a small development set. A cheap reasoning model on its own, Jeff with a
reasoning model for anything it wasn't sure about, and a reasoning model proposing answers with Jeff checking them on about 200 held out families. The cheap reasoning model on its own did as
well as Fable for about 2% of the cost. Jeff first got the core answers right, but it missed nine household legs because it had confidently said no to every one of them. So we rewrote the
questions without touching the models or the thresholds. The household question now said what counts as enough evidence. And Jeff went from no on all 13 development questions to yes. And as we
scaled it statewide, we ran over a dozen rounds of such qualification. Each round fixed a definition. What a committee is, what a filer means, when two people live at one address, what does that mean?
Every one of Ohio's 23,317 cases now has a label that says what the answer rests on and how far it was checked. This is the hierarchy we discovered for this specific problem.
And here's everything we learned about putting decision models into pipelines. I'll leave this up so you can screenshot it. But here's where the money went. The whole statewide job came to $7.95 on an
$800 budget that was set ahead of time. Checking cost about four times as much as doing 545 on second opinions, settling disagreements, and the audit against 128 for first answers. And
before Jev, we expected this work to cost about $10,000. And now that the pipeline is built and verified, we expect the audit budget for the next state to be close to zero. The most
amazing thing is that our agent 4A running on Astra and then later on Opus found most of these approaches incrementally on its own by building the system, running it, debugging it, and
trying new things. It ran for 10 days, tried over a dozen architectures. Its Hanks ran for more than 4,000 times alongside 90,000 calls to Jeff, tried practically every model on the Paro
frontier, and the models inside those runs went through roughly 6 billion tokens. And once all of that was done, we wrote what we learned back into our library of agentic patterns. This work
leaned on these existing ones and we're adding new tested ones like the checking letter. This is to me the value of taking work off the main thread for humans and for
agents because every single one of these iterations was a version controlled hank. They were easy to revert, understand, debug, and critique. So, can models do this natively now? Not quite.
They're missing four things which we'll we'll go over. And there's something that doesn't go away though as models get bigger and more capable. The prior just like humans, models bring their own
priors, their beliefs about what should be in the world to every task. This is the fourth schema that I mentioned before, the one the model brings with it.
Bigger models in a strange way are worse at this. Sometimes they hold on to their beliefs and argue for them even more vehemently. Here's a few that we ran into. One pipeline looked for inind
spelled with an underscore. The file spelled it with a capital I and a hyphen. So the model counted 15,658 in kind contributions as ordinary money didn't double check the loan payment
repayments also disappeared the same way. Another one tried four date formats when the file used the fifth 99.4% the transaction dates then came out empty and every row count and dollar so
matched. So the agent moved on. Several runs noticed that loan amounts were negative. Decided that the sign was redundant and stored the absolute value and net of 784,000 became 5.3 million of
debt in the end validated by multiple models. And this is quickly becoming the largest class of error I see across companies at data work as models take over. Sometimes you can solve this just
by not vibing by checking results and applying human intuition. And what you're actually doing there when you do this is interesting. You're intersecting your priors with the models in that
first example. Any human would catch missing in kind contributions if they knew campaign finance or think to check. It's how we found it. But humans speaking as a human on this particular
task are expensive. They are slow. They pause timelines. They're even more nondeterministic than models and they hate interruptions. And but it turns out you can also get
really far with cross model prior intersection on our 200 held families. Jev and Luna agreed on 194 and none of those shared answers was wrong. Every error sat in the six families where they
disagree. Models from different families, different pedigrees tend to disagree more and have different priors than models in the same group. For example, the exception, I'm not going to
say who are models that are distilled outside the same company. So with that kind of work, you can shrink the surface quite a bit and the errors along with it down to a much
smaller but persistent class of problems that applied to LLMs as a species. So in one benchmark, four different model families produced the same total down to this end because they all shared a sign
convention that the answer key didn't. And once you get that far, the only way forward is to list them, look out for them, and apply specific solutions. So going back, what are the four things
we're missing to be able to self-optimize? Number one is a stable deployment surface. We use Hank for this, a harness that takes the fastmoving surface of
agent runtimes like cloud code and PI and that exposes a consistent well- tested log and API interface with checkpointing, roll back, budget enforcement, everything built in.
Something you can build on. But other things fit this description. To be fair, for headless data work, Hankwave, I would say, is still the oldest, most stable, and the most open.
I'll leave the skill up if you'd like to try it. Number two is some way to bound your experiments. You can't test unless you can control cost, time, and access as resources. The third one is knowhow
and methodology. We found that this new class of models can take everything we've learned from two years of deployments, agentic patterns, debugging techniques, prompting and apply it to
complex problems. With the right abstraction layer, you can express it very token efficiently and the models can implement it. The fourth and the most important one is a failure surface.
Our committee said, give me a place to stand and I will move the earth. And in our case, we haven't met a problem or a constraint that we couldn't iterate ourselves to solving given a stable
stack to build on and a failure surface to iterate against. That last one has been the hardest to put into words and into tooling and instructions that helps models get there. The current best
models are still only barely good at this sparks of intelligence, so to speak. The whole process though involves going through six stages. First, we spec the job and we split it. For Jeff, that
means splitting some 800,000 rows into 200,000 smaller specialized cases and each of those cases into typed questions. What kind of donor, one donor, you know, different different
questions that needed to get answered. Then we decide the failure surface. In this case, we ran good models on a small slice of the data with some of it being manually checked to set a baseline that
we can fail against. In other cases, we've set automated failure systems. We've set schema checks. We've also covered behavior as a thing that we can measure against. But it's very important
to have to define a failure surface before you ever start. But now comes the fun part. We run minimal bounded pilots to test architecture. And once something starts working, we move those checks
into rigs. Code that runs between bounded work segments that we call codons. These codons are then reused, looped independently, validated, and placed in sequence.
Finally, working pipelines get deployed to production where they can slowly mature. And that middle part is where the surfing happens. We find an architecture that gives a solid result.
We use it as a baseline. Then we swap models and some other parts for faster, cheaper options, compare against known intermediates, tighten the requirements for success each time, moving closer and
closer to the ideal, and you just watch the frontier move. Being able to break a complex problem into pieces means each piece can move its own to its own best position. As Adam Smith would say in a
system like this, ontologies exist as intermediates between intelligence and result, which makes them easier to reuse. That's the other half of what I mean by just in time ontologies. It's
built when the job needs it, kept with its receipts, and reused when the next job needs the same thing. And once you have those, you can make these things cheaper. You can you can run them in
parallel across data sets to scale up. I close with an apology, right? That the answer is there is no ontology. Not a universal one, at least there never was one. The good news is that this makes
every ontology and schema valid as long as you can label and preserve the context around it. And if we can harness this cheap intelligence is starting to percolate through the world around us,
we're rapidly approaching a future where any information in any format is made as useful as it can be. And at Subridge, we're working as hard as we can to make that future a reality. Thank you.