Videos
| Thumb | Title | Channel | Status | Published |
|---|---|---|---|---|
|
Mistral's 1 Trillion Model Is Coming. Will It Fit Your PC?! #shorts
Mistral Large 4, a 1.05 trillion parameter mixture-of-experts model, will not fit in consumer hardware: its 4-bit... |
Cloud Codes | summarized | 2026-10-08 09:46 |
|
Ling 3.1 Flash First Test – Is THIS Really a DeepSeek Competitor?
Ling 3.1 Flash, a 560B parameter MoE model from Ant Group, delivers acceptable but not outstanding results across... |
Bijan Bowen | summarized | 2026-10-05 15:35 |

|
Best Local Coding AI for Your GPU (4GB to 512GB)
Fitting a model on your GPU is not enough; you must also account for KV cache and runtime overhead. For most... |
Cloud Codes | summarized | 2026-09-20 12:00 |

|
Qwen 3.6 35B on 3GB RAM?
Edge Zero's 2.9 GB memory claim for running Qwen 3.6 35B is technically accurate but misleading: it measures what... |
Cloud Codes | summarized | 2026-09-15 19:30 |
|
DeepSeek V4.1 Flash Is INSANE – Is THIS the Best Open Model Yet?
DeepSeek V4.1 Flash is a significant open model with a 552B parameter mixture-of-experts architecture,... |
Bijan Bowen | summarized | 2026-09-10 15:23 |
|
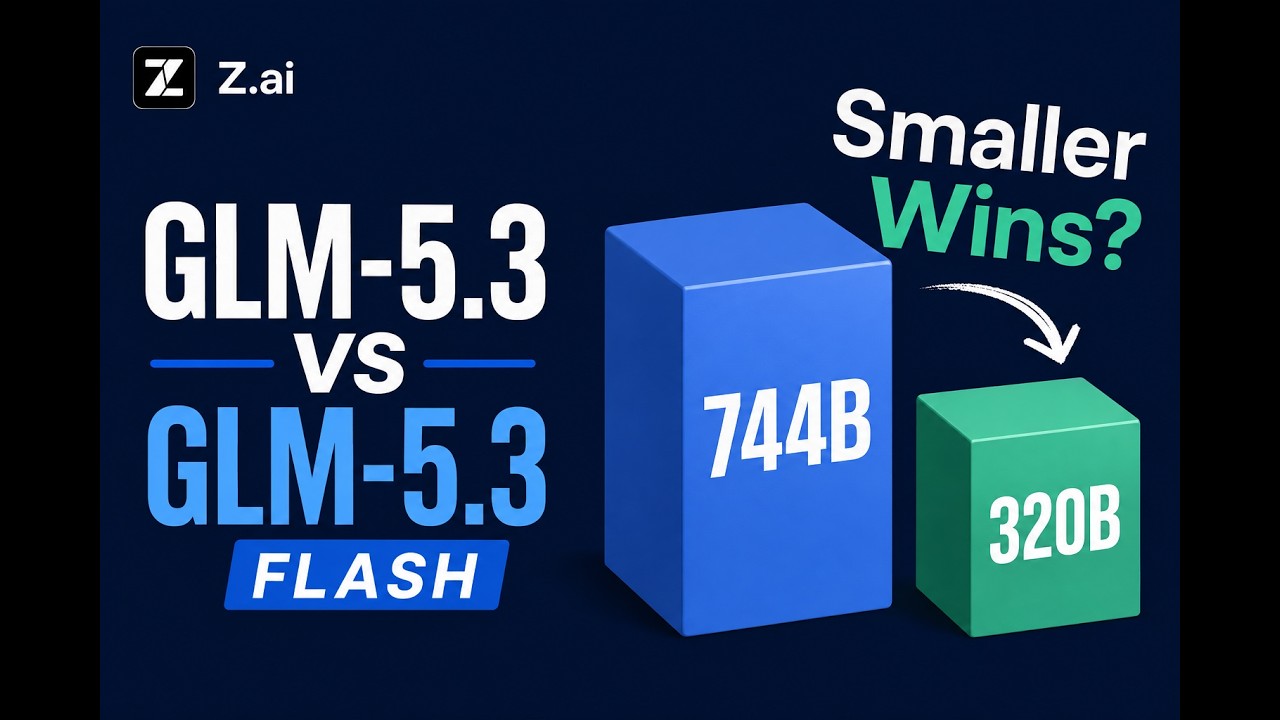
GLM 5.3 Flash vs GLM 5.3: When Cheaper Is the Right Call
GLM 5.3 Flash delivers near-flagship performance at roughly 1/9th the cost of GLM 5.3, but its heavy token usage for... |
Sam Witteveen | summarized | 2026-08-30 15:20 |

|
New Local AI Engine Everyone Will Be Using in 2027 ? (FreeToken)
FreeToken's routing-aware expert caching cuts cache misses to 16% versus 62% for llama.cpp's static split,... |
Cloud Codes | summarized | 2026-08-22 19:00 |

|
Run Ornith 1.5 35B Locally: 155 Tokens/Sec on Your GPU?
Ornith 1.5 35B is a capable local coding model that fits on a 12-24 GB GPU, but the viral claim of 155 tokens/sec on... |
Cloud Codes | summarized | 2026-08-20 16:30 |
Frontier News · by Hyperjump Technology