Videos
5 total
| Thumb | Title | Channel | Status | Published |
|---|---|---|---|---|
|
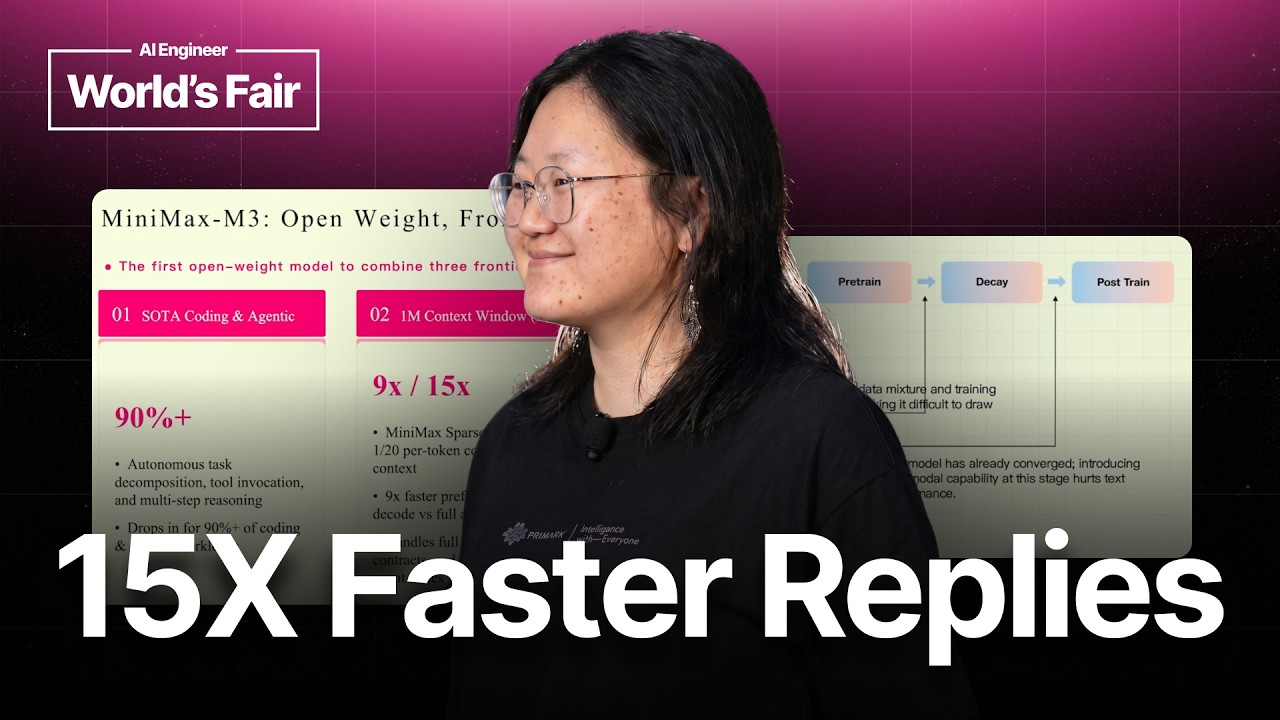
How MiniMax M3 Was Built: Sparse Attention and Native Multimodality — Olive Song
MiniMax M3 achieves 9x faster prefill and 15x faster decode than full attention by using block-level sparse... |
AI Engineer | summarized | 2026-10-10 22:30 |
|
DeepSeek V4.1 Flash: The Architecture That Crushed Cache Costs by 437×
DeepSeek V4.1 Flash cuts per-token cache memory from 389,000 bytes to 890 bytes — a 437× reduction — by rebuilding... |
Cloud Codes | summarized | 2026-09-12 19:30 |
|
Inside K2 Horizon: The 4B Model That Beat 550B
K2 Horizon MUA's mixture-of-value-experts architecture routes 4 of 64 value experts per word, yielding 4B active... |
Cloud Codes | summarized | 2026-09-07 19:30 |
|
Why AI Agents Need Million-Token Context — Thomas Wolf & Olive Song, MiniMax
MiniMax's M3 is the only top-five open-source model that is truly multimodal, packing a 1 million-token context,... |
AI Engineer | summarized | 2026-09-04 13:00 |
|
How DeepSeek Cut AI Coding Costs to $0.14
DeepSeek V4 Flash achieved 14-cent million-token pricing through native sparse attention, compressed KV cache, and a... |
Cloud Codes | summarized | 2026-08-06 16:00 |
Frontier News · by Hyperjump Technology