Enjoying this issue?
Get tomorrow's AI & engineering digest in your inbox — hand-picked, summarized, and always spam-free.
TLDR
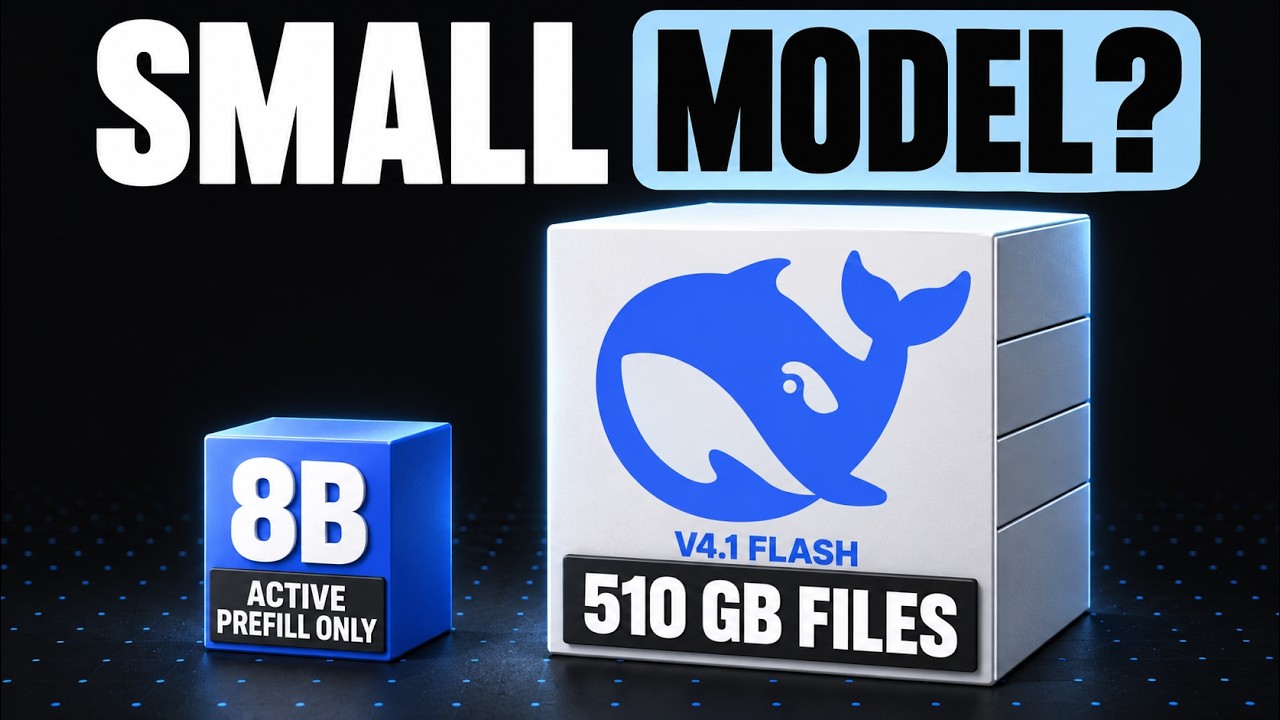
Running DeepSeek V4.1 Flash locally requires at least 510 GB of storage and a multi-GPU setup costing tens of thousands of dollars, with no demonstrated cheapest build. The model's 8B active parameters during prefill and 16B during decode don't reduce the memory needed for the full 552B parameter checkpoint. The API is far cheaper for most workloads, making local ownership only justifiable for privacy or offline access.
Key points
DeepSeek V4.1 Flash has 552B total parameters but only 8B active during prefill and 16B during decode.
The published weight files total about 510 GB, with Ingram memory occupying 203 GB.
A four-card RTX Pro 6000 Blackwell setup costs $64,000 just for GPUs, and no working configuration has been demonstrated.
The API costs $0.21 for 1M input and 100K output tokens off-peak, far cheaper than local ownership.
No cheapest working local build has been established; hardware arithmetic alone cannot settle the cost.
Tools mentioned
Techniques
- Mixture of Experts
- conditional computation
- KV cache
- model parallelism
Stop scrolling. Start reading smarter.
Receive the day's most important AI & engineering updates in one concise email. No spam.
Transcript (captions)
DeepSeek has published V4.1 flash and the files alone add up to about 510 GB. That's where your local budget starts. The release describes a model that activates only part of its parameters
for each token, but your computer still needs somewhere to keep the rest. Before buying hardware, we need to follow those files into a working runtime, then price the machine and the work it can finish.
There's no tested cheapest local build in the sources checked on September 10th. The published inventory, reference code, and dated prices let us investigate the budget. Electricity and
API calculations will give you running cost examples. A particular computer still needs to demonstrate the complete model at a speed you would accept. Start with the active parameter count.
DeepSeek reports 8 billion active parameters per token while processing the prompt. This stage is called prefill. During decode, when the model generates its answer, the reported
active count rises to 16 billion. Those figures describe the work selected for a token. They can't be used as the size of the checkpoint you need to download or the memory budget for a running service.
Picture one token taking a route through selected experts. The other experts remain stored even while that token bypasses them. The route can be narrow while the surrounding inventory stays
large. This is the distinction that matters for your wallet. Selective computation can reduce work without making all the inactive weights disappear. Our route is a conceptual
illustration of that distinction, not a recorded trace through this model. DeepSeek has 552 billion backbone parameters with Ingram memory described separately. Ingram is the conditional
memory part of the design. Keeping those categories separate avoids treating every stored value as the same kind of computation. The architecture also separates prompt processing from answer
generation. A single active count would hide that difference. For the storage question, the published files give us a more concrete starting point. The repository lists 48 weight files. Adding
their advertised byte sizes gives about 510.3 decimal gigabytes. That inventory hasn't been downloaded and tested here. It tells us the size of the listed files
before adding the tokenizer code or temporary space needed to prepare them for a runtime. Your operating system may display the same bytes as roughly 475 gigabytes. The files haven't become
smaller, the unit changed. The tensor payload total also excludes some file overhead. Keep the full file total attached to the download and runtime memory as an unanswered measurement. Two
of the published shards map to Ingram entries. Together, those files occupy about 203 gigabytes. The remaining files occupy about 307. These are groups in the release
inventory. The Ingram associated group includes supporting tensors as well as embeddings. So, calling the entire group pure lookup tables would overstate what the index shows. Every byte still
belongs to one of the two groups. That split suggests an engineering question. Could the Ingram associated material live in ordinary system memory while other weights stay on the graphics
cards? Such a route could change which memory you need to buy. It needs a working implementation, including the movement of whatever the accelerator needs for each step. A file index
describes how material is packaged. It doesn't choose the device where the program will allocate it. In the supplied reference, the model is constructed on CUDA and the Ingram table
follows that device context. A proposed route into host memory therefore stops at a software requirement. The inspected code doesn't demonstrate that offload. Other implementations may provide a
different route. Before assigning the large Ingram group to inexpensive memory, require the exact engine and release revision, a completed inference run, and measured allocations.
Otherwise, the cheapest part of the proposed build depends on software that hasn't been demonstrated in these sources. Compression needs the same care. The published configuration
already declares 4-bit expert weights. The release also contains other formats and supporting data. Taking the whole download and having it again because a calculator offers a 4-bit button would
count as saving that hasn't been demonstrated. A usable compressed release needs its own exact files, supported runtime, and quality evidence. A parameter multiplication alone can't
supply those things. DeepSeek also reports a very small global key value cache, 890 bytes per token. This cache is one part of the live state used while handling a context. Keep the word global
attached to it. That component excludes the weights, other caches, working buffers, and the surrounding process. At exactly a million tokens, the reported global cache rate multiplies to less
than 1 decimal gigabyte. On screen, that small allocation sits beside the much larger weight inventory. Shrinking the cache changes its own part of the accounting picture. The weights remain.
This is how a model can have a striking cache efficiency claim while still asking you to plan for hundreds of gigabytes of published material. The reference runner adds another boundary.
Its inspected interactive setting uses a sequence length of 65,536. An advertised model capability and an example configuration can differ. Ask what prompt length a local demonstration
used and how much memory it occupied. A short successful prompt doesn't establish the resources for the longest context. There's preparation work before generation, too. The supplied conversion
code writes a checkpoint for each parallel rank and converts some projection weights to a different format. So, you need room for the source files and a conversion process whose
actual output and peak memory have been checked. Buying storage for exactly the download total leaves this stage unpriced. The converted checkpoint is a separate artifact with its own
allocation questions. DeepSeek calls the supplied runner a readable reference implementation. Its example uses model parallelism of eight, and its generation path uses ordinary auto regressive
sampling. That gives developers a path to inspect. It doesn't establish an eight-card minimum, identify a validated graphics card model, or supply a speed result. Treat the example as
instructions whose execution still has to be demonstrated on the proposed system. We can now attach prices to a hardware scenario without pretending the scenario has passed that test. Nvidia
specifies 96 GB of memory for the RTX Pro 6000 Blackwell workstation edition. Its US marketplace listed this edition at $16,000 out of stock when these sources were checked. That's a dated
card listing. It is neither a complete system quote nor a promise that a seller can deliver today. At that listing price, four cards total $64,000. Keep cards only and untested attached to
the amount. The subtotal buys no demonstrated offload route. The rest of the receipt is still open. Host memory, processor, storage, chassis, links, cooling, and power delivery. Taxes and
setup also remain outside that card subtotal. Those blank lines are unquoted costs, not free components. The four-card proposal needs converted weights that fit their assigned devices
with room for live allocations. Host memory needs a functioning path to the accelerators. Placement and transfer speed affect whether the result is useful. Until those measurements exist,
adding advertised memory capacities can't validate the proposed build. If we illustrate eight cards at the same listing price, the cards alone total $128,000.
This connects a price to an eight-device inventory. It doesn't prove that this particular card runs the reference successfully. The example in the documentation doesn't specify that
model. Quoting the total as the minimum cost would turn several open engineering questions into a false answer with a very precise dollar sign. A high-memory desktop creates a different pricing
mistake. Apple announced an M5 Ultra Mac Studio starting at $5,499. Its announcement places the 512 GB option in late October. At the September research date, that option is a future
configuration. The starting price and the largest memory option belong to different claims. They can't be combined into a quote for that machine. Even with a matched quote, you would still need a
runtime that executes this release on that platform, the exact files it accepts, and a memory profile with room for the system. The photograph identifies the desktop. It can't
demonstrate installed memory or compatibility. Check the program before committing to the memory upgrade. Once a working system exists, electricity is straightforward to calculate from
measured inputs. Use average power at the wall for the whole system, how long it runs, and your tariff. Nvidia specifies a maximum board power of 600 W for the card discussed here. That rating
isn't a measurement of this model running, and it's in the wall draw of a complete multi-card computer. Keep it out of the example unless you measure the relevant system. For a worked
example, assume the whole machine averages 1 kW while used 8 hours a day. Over 30 days, that gives 240 kW hours. Replace those assumptions with your own usage and wall measurements. If the
machine stays available outside the active hours, count its remaining energy use, too. With an assumed tariff of 15 cents per kW hour, that example costs $36 for the month. It excludes
separately powered cooling and other ownership costs. No particular DeepSeek build has supplied the assumed power figure. Change the draw, hours, or tariff to see the effect on your bill.
Purchase costs remain separate. The API gives us a dated alternative that we can price for a defined workload. DeepSeek maps its hosted flash service to this release on the inspected pricing page.
Start with 1 million uncashed input tokens and 100,000 output tokens, all billed off-peak. This is an example bundle of work, not a claim about how many prompts you personally send. Its
input and output quantities stay fixed while we build the bill. The published off-peak input rate makes that input cost 15 cents. The output at 60 cents per million tokens adds 6 cents for our
smaller output quantity. Together, the example costs 21 cents. Output matters. A price quoted only for input leaves out the generated answer. For your own comparison, include the output the
service bills, and include repeated attempts in the workload you're actually paying to complete. Caching changes the input line. If the entire example input qualified as cache hits, its charge
would fall to 3/10 of a cent at the published off-peak rate. The output stays at 6 cents, giving a total of 6.3 cents. Full cache hits are an assumption in this variation. You can't apply that
lower input price to every prompt merely because the service offers caching. The inspected peak rates are twice the off-peak rates, so our uncashed example becomes 42 cents during those windows.
Deep Seek list the peak schedule in UTC. A local clock comparison needs that time zone conversion. The rate doesn't follow your idea of the working day. Keep the date and billing conditions attached
when saving this calculation because a provider can change its price page after the video is published. A thousand repetitions of the uncashed off-peak bundle would cost $210 at those rates.
That gives you a scale for a chosen workload. It says nothing about whether a proposed local computer can finish the same volume in a month. For that comparison, both routes need the same
task mix, usable quality, and acceptable waiting time. Owning memory doesn't guarantee you enough throughput to replace a service. Local ownership adds the purchase and setup cost, spread over
the time you expect to keep the machine, with any expected resale treated as an estimate. Then add electricity, maintenance, and the time spent administering it. If you already own
suitable hardware, calculate incremental operating costs separately. That can make experimentation reasonable without pretending the original purchase was recovered. The question changes
depending on whether you're using an existing machine or ordering a new one. Break even comes after the runtime and workload are established. Compare the monthly cost you need to recover with
the API cost of the same work. If you model local variable cost per workload, subtract that from the API price before dividing. When local variable cost already equals or exceeds the service
price, doing more of that work can't repay the purchase through usage savings. There's no supported payback date to announce from the evidence here. Privacy, offline access, and control can
still justify owning a system. Those are reasons to accept a cost even when ownership isn't the cheapest way to generate tokens. For an existing machine, a bounded experiment can
establish what runs and where it fails. For a new purchase, require the demonstrated configuration first. Complete release, exact runtime, measured peak allocations,
representative prompt and output, and a result you can evaluate at normal speed. So, the useful cost answer for V4.1 flash begins with a large published inventory and a software requirement
that hardware arithmetic can't settle. The expensive card subtotals are conditional examples. The low API bill belongs to a specified workload. A cheapest working local build remains
unestablished in these sources. Before spending money specifically for this model, get the reproducible run and the complete quote for that same configuration. Those two artifacts are
what would turn this investigation into a buying decision.