Videos
| Thumb | Title | Channel | Status | Published |
|---|---|---|---|---|
|
Stop Renting Intelligence: The Train-to-Deploy Loop for Specialized AI — Fireworks AI
Fireworks AI is selling the full train-to-deploy loop for open-source models, and the pitch is built on scale... |
AI Engineer | summarized | 2026-10-11 22:30 |

|
Turning My Obsidian Vault Into a Local AI Engineer — Filip Makraduli, Superlinked
An MCP server that routes document processing tasks from Claude Code to a private Superlinked inference cluster can... |
AI Engineer | summarized | 2026-10-11 12:00 |

|
They Switched to 16 DGX Sparks (Running 2.8T AI at Home)
A builder is running Kimi K2, a 2.8 trillion parameter model, on 16 Nvidia DGX Spark boxes at about 21 tokens per... |
Cloud Codes | summarized | 2026-10-06 15:36 |

|
Qwen3.8-Flash-Next at 45 Tokens/sec on a 12GB GPU?
Strata, an Engine 1 developer's inference engine for Qwen-3 8B Flash Next, claims 44.8 tokens/second on a 12GB RTX... |
Cloud Codes | summarized | 2026-09-28 12:00 |
|
Same AI Model. 40% Cheaper. Here’s How.
Unreal Labs' Unreal Agent claims up to 40% lower inference cost than Codex on Terminal Bench 4.0 by changing the... |
Cloud Codes | summarized | 2026-09-25 05:30 |
|
Two Bugs That Hid in Plain Sight: A vLLM Debugging Detective Story — Asaf Gardin & Yuval Belfer
vLLM's Mamba state cache had two silent bugs—decode-before-prefill scheduling and uint32 index overflow—that... |
AI Engineer | summarized | 2026-09-19 18:30 |

|
Large clusters for small models — Daniel Svonava, Superlinked
Small open-source models can match or beat frontier models on specific tasks at a fraction of the cost, but serving... |
AI Engineer | summarized | 2026-09-19 17:30 |

|
Vertical Mobility: Inference from MVP to Trillion-Parameter Workloads — Sitanshu Gupta, CoreWeave
CoreWeave's inference platform is built around two consumption models, serverless and dedicated, with serverless... |
AI Engineer | summarized | 2026-09-19 16:30 |

|
Are LLM Performance Benchmarks Reliable? — Ashok Chandrasekar & Jason Kramberger, Google
Standard LLM benchmark harnesses often fail to deliver the requested load and inflate latency, making server... |
AI Engineer | summarized | 2026-09-19 16:00 |
|
Routing LLM Inference in Production: From Engine Signals to Policy — Qianru Lao & Lu Zhang, OpenAI
OpenAI's inference load balancer evolved from a feedback-loop-based P controller to a control plane/data plane... |
AI Engineer | summarized | 2026-09-19 15:30 |
|
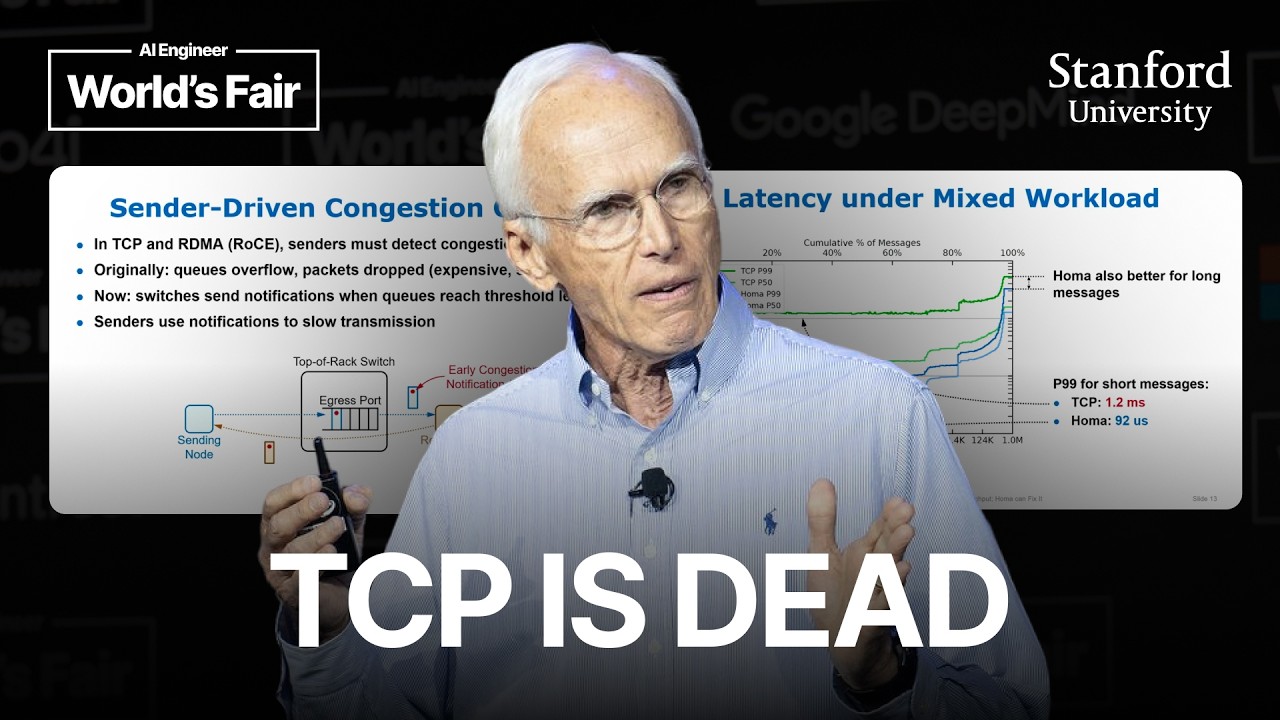
The End of TCP for AI Clusters — John Ousterhout, Stanford
AI workloads are shifting from large transfers to small messages, making latency critical. TCP and RDMA suffer from... |
AI Engineer | summarized | 2026-09-17 13:00 |
|
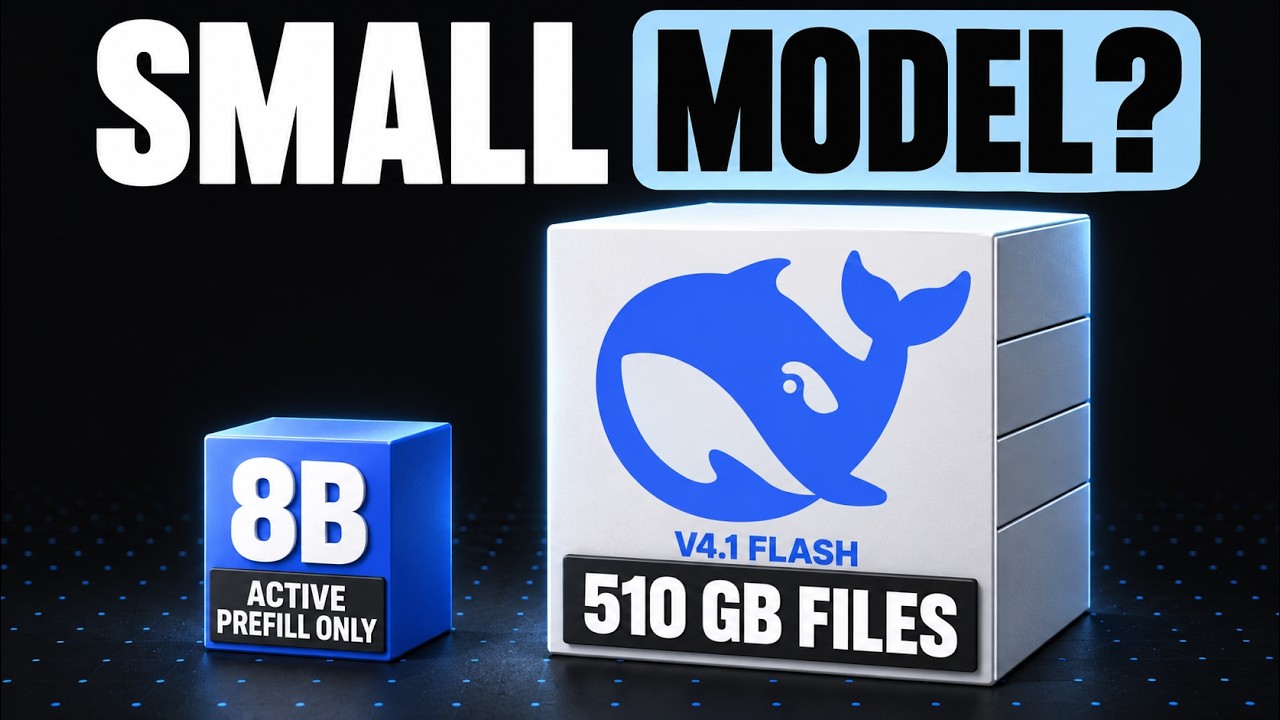
What It Costs to Run DeepSeek V4.1 Flash Locally?
Running DeepSeek V4.1 Flash locally requires at least 510 GB of storage and a multi-GPU setup costing tens of... |
Cloud Codes | summarized | 2026-09-11 19:30 |

|
Everyone Got NVIDIA PAIR Wrong
NVIDIA PAIR is not a GPU pooling tool that combines memory across machines. It is a request-level load balancer that... |
Cloud Codes | summarized | 2026-09-06 10:09 |

|
The Inference Frontier: from 100 to 10,000 tokens per second — Sean Lie, Cerebras CTO
Cerebras CS4 runs GPT-4 at over 4,400 tokens per second, and the upcoming CS5 targets 10,000 TPS for medium models... |
Latent Space | summarized | 2026-09-02 17:05 |

|
Full Analysis: OpenAI Jalapeño chip..
OpenAI's custom inference chip, Jalapeno, designed with Broadcom in 13 months, shows preliminary benchmarks that... |
Caleb Writes Code | summarized | 2026-08-27 22:56 |

|
KV Cache-Aware Routing and P/D Disaggregation on Kubernetes — Yuchen Fama & Ashish Kamra, Red Hat
LLMD's KV cache-aware routing and prefill-decode disaggregation address the chaotic inference patterns of agentic... |
AI Engineer | summarized | 2026-08-27 14:00 |

|
Qwen is cooking customer AI..
Qwen 3.8 27B, a 27-billion-parameter model from Alibaba, achieves benchmark scores near GPT-5.6 Luna and Opus 4.6... |
Caleb Writes Code | summarized | 2026-08-26 12:48 |
|
Preferences Over Benchmarks: Model Routing — Archana Kamath & Tyler Gillam, DigitalOcean
Picking a single 'best' model based on benchmarks is the wrong approach; the right model depends on the specific... |
AI Engineer | summarized | 2026-08-22 15:30 |

|
The Real Reason Why Stripe Bought OpenRouter
Stripe's acquisition of OpenRouter is a bet that AI inference will become a major economic flow, similar to... |
Cloud Codes | summarized | 2026-08-20 19:30 |

|
Generative Video at the Speed of Light — Keegan McCallum, uRun
Generative video models are now efficient enough to generate video faster than you can watch it, at a fraction of... |
AI Engineer | summarized | 2026-08-18 16:30 |
|
Qwen3.8-27B & How to Serve it Fast
Qwen released the 27B parameter Qwen3.8-27B model, which significantly outperforms its predecessor Qwen3.6-27B and... |
Sam Witteveen | summarized | 2026-08-18 13:00 |
|
Open Source Is Dead. Long Live Open Source. — Saoud Rizwan, Cline
Saoud Rizwan, founder of Cline, argues that the open source community is dying due to AI-generated spam and security... |
AI Engineer | summarized | 2026-08-07 23:26 |

|
The Inference Frontier: 10x Faster Models to Self-Optimizing AI — Philip Kiely & Ali Taha, Baseten
Inference engineering for large language models involves a stack of optimizations including KV cache-aware routing,... |
Latent Space | summarized | 2026-08-03 21:35 |

|
Run "Kimi K3" on a Laptop With 32 GB Ram (No GPU Needed)
Waste is a 6,000-line C engine that runs the 2.78-trillion-parameter Kimi K3 mixture-of-experts model on a laptop... |
Cloud Codes | summarized | 2026-08-01 16:00 |

|
"Stop prompting, start building LOOPS." - swyx
Building agent loops is the new prompting. Developers should focus on creating verification loops and specifying... |
David Ondrej | summarized | 2026-07-09 16:14 |

|
The 100,000 Sandbox Problem — Akshat Bubna, Modal CTO
Modal is a cloud platform built for AI workloads, focusing on elastic inference, sandboxes, and training. They've... |
Latent Space | summarized | 2026-07-08 22:42 |
|
$1000 Budget Local Ai Rig
A Dell Optiplex motherboard can be transplanted into a custom frame to create a budget local AI rig for under $1000,... |
Digital Spaceport | summarized | 2026-07-06 14:00 |

|
I Built a 32GB Local AI Server for $1,500
A $1,500 32GB VRAM local AI server built from three RTX 3060s (12GB+12GB+8GB) performs surprisingly well for LLM... |
Digital Spaceport | summarized | 2026-06-18 14:00 |
Frontier News · by Hyperjump Technology