Enjoying this issue?
Get tomorrow's AI & engineering digest in your inbox — hand-picked, summarized, and always spam-free.
TLDR
AI workloads are shifting from large transfers to small messages, making latency critical. TCP and RDMA suffer from high tail latency due to incast congestion. Homa, a new protocol from Stanford, uses receiver-driven congestion control and priority queues to reduce tail latency by an order of magnitude, outperforming TCP even on large messages.
Key points
AI inference and agentic workloads increasingly involve small message exchanges where latency matters.
TCP and RDMA experience high tail latency due to incast congestion and sender-based congestion control.
Homa is a message-based protocol with receiver-driven congestion control and priority queues.
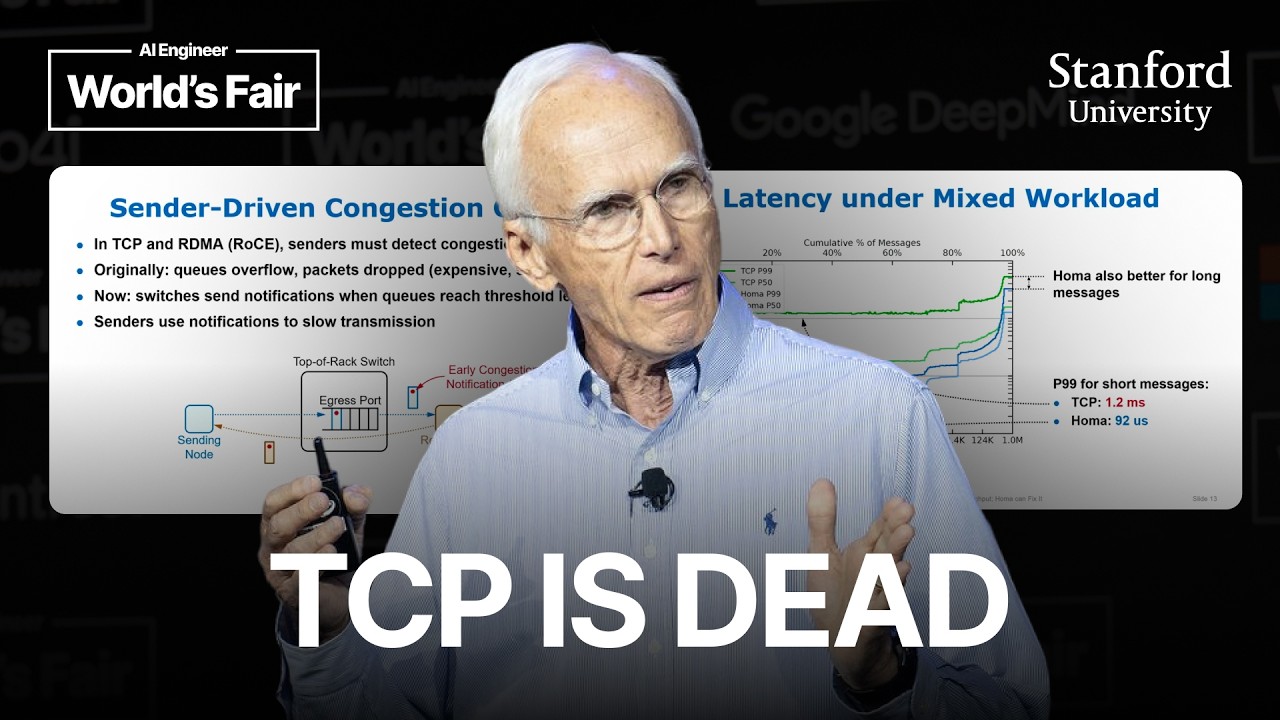
In benchmarks, Homa's P99 latency for short messages is about 13x better than TCP.
Homa is available as a Linux kernel module and is being upstreamed.
Tools mentioned
Techniques
- receiver-driven congestion control
- shortest remaining processing time first (SRPT) scheduling
- priority queues
- message-based transport
Stop scrolling. Start reading smarter.
Receive the day's most important AI & engineering updates in one concise email. No spam.
Transcript (captions)
[music] Please welcome to the stage the professor emmeritus at Stanford University, John Sterhout.
Good morning. It's really great to be here to talk about the network side of AI applications and in particular to make the case that latency matters and it's probably going to be mattering more
in the future. But I just want to say this is a talk is unusual for me. I've never before given a talk where there are fog generators in the auditorium. Just a really San Francisco experience,
I guess. So, it's it's well known that AI workloads depend on really great networking performance in order to achieve their own performance. And of
course, that's because the workloads are so large that they have to be distributed across machines and then you have to communicate between the machines. But what I want to talk about
today is that it seems that those workloads are changing. And so I hope to do three things over the next 15 or 20 minutes. First to convince you that in fact the workloads are changing and that
whereas the workloads used to be completely dominated by large transfers where throughput is the key metric that matters that we're seeing more and more smaller transfers where the latency is
crucial. The second thing I hope to do is to convince you that legacy protocols like TCP and RDMMA are poorly suited to this environment. They weren't designed for
this environment and unfortunately they suffer from very high tail latency when you mix small messages with large ones. I'll talk a little bit about why that's the case. Then third, I'd like to
introduce Homo which is a new protocol we've developed at Stanford that actually was designed in a clean slate redesign to handle data center workloads like these and in fact it does quite
well on those workloads and can reduce tail latency by an order of magnitude or more. So I'll tell you a little bit about Homa. So let's dive in. First, workloads. Historically,
AI workloads have consisted of enormous transfers between machines, and that's all that really mattered. Gigabytes of data for things like weight gradients and and so on.
In these workloads, what you really care about is throughput, how many gigabits per second you can pump through the pipes. And these are relatively easy workloads for networks because if it
takes a while to set up the connection and start the transfer, it doesn't matter. The transfers go on for so long that all that really matters is the throughput. And so in these
environments, TCP and RDMA perform pretty well. Uh, by the way, when I say RDMA, what I really mean is Rocky RDMA over converged Ethernet, which is the underlying transport that's used by RDMA
for most purposes today. So anyhow, the old workloads, big transfers, throughput matters, uh the legacy protocols work pretty well. However, it appears that the workloads
are changing. They're becoming more granular with smaller chunks of computation and smaller exchanges of data. And this seems to be particularly true in the world of inference and also
in agentic workloads. Not so much for training workloads are still massive transfers. And so what's happening is that more and more there are small message exchanges typically for things
like metadata and coordination such as checking to see if a particular entry is present in a KV cache that's distributed or doing barrier synchronization at the end of periods of compute. And for these
workloads what really matters is latency. That is what's the roundtrip time to send some small piece of data across the network do a little bit of computation and get a small result back
again. And in fact, it isn't just just latency or average latency that matters. What really matters is tail latency. That is, you'd like to know that if we send a whole lot of small messages, all
of them will complete quickly. So, for example, we typically measure things like 99th percentile latency. And if we have high tail latency, that can limit the overall throughput of the system.
So, here's an example. Suppose a common thing is to take a workload and split it up across several nodes which do intensive computation using their GPUs for some period of time
and then once they've all finished their computation you do some small exchange between the nodes exchange data meta data and then it'll go on to the next round of computation
and while that exchange is happening that synchronization is happening the GPUs are sitting idle so if even one of those exchanges takes a long time. It turns out the whole
process stalls. You need all of those exchanges to complete before you can go on to the next phase of computation. Now, if the computation phase is say 5 seconds and it takes a few milliseconds
for the exchange, you know, not a not a problem. And that's historically what it's been. But now with agentic workloads where you're trying to pump out tokens relatively rapidly at a
regular rate, the periods of computation are getting down into sort of the millisecond time scale. And if it also takes milliseconds to do that synchronization, then you're wasting a
significant fraction of your GPU resources waiting for the the synchronization to occur. So I'm curious. I'd like to just do a a quick audience poll here. Is there anybody
here where you have reason to believe that the latency of small messages is impacting the overall throughput of your applications? If so, can you just raise your hand? See, is there anybody out
there today? Actually, more hands than I expected. So quite a few people out there are raising their hands. I think this problem is likely to get worse as the trends continue.
So what's going on? Why is tail latency bad? Well, typically the cause is congestion resulting from incast. So incast is when several nodes all decide simultaneously to transfer data to some
destination node. And if they all send large messages, well, the links are the same everywhere in the network. So three nodes can transfer three times as fast as one node can possibly receive. And so
what happens is that packets accumulate at the last hop going to that destination in the top of rack switch at its egress port for the destination node.
Then if some other node decides it wants to send a short message to that same destination, the short message gets stuck behind the long ones in the queue there. And actually that causes delay
and in the worst case so many packets arrive that the switch runs out of buffer space that it has to drop packets and then there are you timeouts and retransmissions that make everything
even worse. So somehow we need some way to reduce the congestion in those cues. Somehow we have to get the sending nodes to stop sending so fast so the cues don't just
build up without limit. So the way this is done historically virtually all network protocols before HOMA including TCP and RDMA congestion control is the responsibility
of the sender. So senders somehow have to figure out that congestion is happening and they have to slow down their rate of transmission. Now you you might wonder why are senders doing it?
because the congestion is way over at the other end of the data center network. How does the the sender find out? Well, in the in the old really old days, the way they would find out is the
cues would overflow and packets would get dropped. The sender would detect the packets got lost because it wouldn't get acknowledgements back and it would assume that means there's congestion and
then slow down its rate of transfer. That's really expensive. So today there are better techniques that mostly involve the switches providing information. So a top of rack switch
when it sees that the Q length for an ingress port has reached some threshold starting to fill long before the queue overflows it starts marking all of the packets that pass through with what's
called early congestion notification ECN marking. And so when those packets pass through to the receiver, the receiver sees the marking in the packets. And then when it communicates back to the
sender next, for example, to send an acknowledgement, then it includes that marking that goes back to the sender. And now the sender sees that the sender realizes, oh, there's congestion
someplace. I've got to slow down my rate of transmission. So that's the basic idea. Unfortunately, getting this right is really hard. Really hard. It's very hard for the
congesture to figure out exactly how to set its rates because it gets one bit of information. There's congestion someplace and there are multiple senders all sending to the same destination.
They're all trying to make adjustments simultaneously. How much do you cut back and how do I know when I can ramp up again? And even worse, it's really hard to do this in a way that's stable
because there's control lag. That is, it takes time before the sender finds out that there's congestion. And in fact, using this process, it typically takes several round trips for the sender to
gradually adjust its rate to get just the right rate to match the available bandwidth. But by the time you do that in a network that things have changed, new transmissions have started or old
ones have finished. And so these systems tend to never stabilize. They're constantly oscillating between sending too much and and sending too little. Now, this problem's been around for a
long time. It's been known in the research community for more than 20 years now. There have been tons of papers published on it. There have been some improvements made. That's
undeniable, but we're still a long ways from anything that works well. And the problem is is with the fundamental nature of it doing the the congestion control on the center side. It just
doesn't work very well. So you end up with a lot of Q buildup. And in fact, you can see the only way to find out that there's congestion is if there's cues and so by that point, we're already
experiencing delays. So that's a problem. There's one other problem with TCP and RDMA also is that their their basic data model is a bite stream just a stream of bytes with no differentiation
in it. So if you send a series of messages say through a TCP socket they get serialized into that stream and on this slide I've you know I've shown the messages appear like they have different
colors in the stream. Well there are no colors in real life. TCP has no idea where the message boundaries are. And that also makes life hard. For example, you don't know how much more data is
coming. If you knew how big the message was, you know how much more is coming. And you can't prioritize short messages, which we'd really like to do. Get the short messages through faster. And you
can end up with what's called head of line blocking where somebody sends a series of messages to the same destination and they send two really large ones and then a small one after
that that gets stuck behind them in that stream and so it gets delayed and again you have tail latency issues. So all in all, TCP and RDMMA are just not well suited to this environment.
So what do we do? Well, what I'd like to do next is tell you about a new protocol called HOMA that we've developed at Stanford, which was based on a completely clean slate redesign for
network transport. If you could start from scratch and rethink how you do transport for data centers, how would you do it? And it turns out in home of virtually every major design decision is
different from TCP and RDMA. TCP for all the amazing things it's done is just not a good match to today's data centers nor RDMA. So what Homa does particularly well is
to manage the combination of large and small messages and to make sure that the messages have short messages have really low latency. So this started off as a PhD
dissertation for one of my students, Benam Montazeri, and then the results were so great that I decided to make it my personal project to see if we could get it out of the lab and into
production. Uh, as you may know, I'm I'm not like most professors and that I love to code. And so I turned this into my my own programming project. I have created a kernel module for Linux. I'm currently
working through the process of getting that upstreamed into the kernel. It's available on GitHub for download. So let me tell you just a little bit about how Homa works. I want to mention three
things. First, it's messagebased, not streambased. [clears throat] In fact, the fundamental unit at Homa is a remote procedure call which consists of two things. A request message sent from a
client to a server and then a response message returned back from the server to the client. So the key thing here is that Homa knows about message lengths. They're buried in the transport all the
way down to the bottom. And this has a bunch of advantages. First, it allows us to predict the future. As soon as a receiver gets the first packet of a message, it knows exactly how much more
data the sender wants to send. And that's so has so much more information for doing congestion control. Second, Home Prioritizes shorter messages. It uses SRPT, shortest
remaining processing time first to try and prioritize shorter messages. And third, because messages are all independent, they're not serialized into a stream. Every message
is independent. Shorter messages can bypass long ones so they don't get cued behind long messages. The second thing about Homa that's different is that it controls congestion
from the receiver. Now, when you think about it, this makes sense because the congestion happens primarily at that last down link to the receiver. And so, the receiver has way more information.
In fact, with Homer, as soon as it gets the first packet of a message, it knows exactly how much more is coming. So, it has essentially complete information about congestion and it can therefore
respond to congestion much more quickly and much more precisely. The way things work with HOMA is that when a sender has a message to send, it breaks it up into packets, but it only
transmits the first few packets, those are called unscheduled packets, to the receiver. Packets after that are called scheduled packets and they only get transmitted when the receiver asks for
them. So the receiver will send grant packets back. It'll paste them out and send those back to the sender over time telling the sender it's now time for you to send me the next chunk of data. And
the receiver can delay those grants. So for example, if the receiver has 10 messages that are incoming, there's no point in sending grants to all 10 of them because then you'll just get
congestion in the in the top of wrap cues. So it can use the grants to reduce congestion and then it can also use the grants to give preference to its most favorite messages which would be the
shorter ones. So it's a way of of implementing SRPT by favoring short messages. The third aspect of Homa is that it takes advantage of the priority cues in
modern switches. So modern data center switches have more than one Q at each egress port typically eight and they can be used in a priority mechanism where packets get transmitted preferentially
from the highest priority Q. So I've shown only two cues on the slide here but typically there's more than that you can specify in packets using the various fields of the packet you can
specify which queue it should go into and so Homa dynamically makes those choices in a way to give priority to shorter messages. So if we go back to the incast example from a few slides
ago, all of those long messages will pile up in the lowest priority queue. But if there's a short message coming, it will use a higher priority queue. And so it will immediately bypass all of the
cued packets from the short from the uh the longer messages and get through to the destination more quickly. So how much of a difference does this make? Here's a this slide. I've got one
sample benchmark that I use as part of my tuning and evaluation of Homa. It consists of a workload of a bunch of machines on a network that are exchanging messages back and forth of
different sizes ranging from very small to very large. And on this graph you can see on the x-axis is the message length from about 50 bytes up to a megabyte. The yaxis shows you the roundtrip time
for messages of that length. So this request this uses request and response messages that are the same length. You can see TCP in green, Homa in blue, and the Y-axis is is roundtrip time. So
lower is better. And for each protocol, I've got two curves. One curve is the P50 curve. That's the median latency for messages of this length. And then P99 is the 99th percentile, i.e. tail latency
for messages of this length. So I want to point out two things. First, the P99 for short messages is dramatically better for HOM. So with TCP it's more than a millisecond tail latency. Home is
less than 100 microsconds about 13 times faster. Second interestingly you might think that because Homa favors shorter messages that long messages suffer and
get worse performance. It turns out that's actually not the case. Even on the longest messages, Hom is almost a factor of two better than TCP. I don't have time to explain that today, but it
has to do with the fact that HOMA uses run to completion approaches which are much more effective than fair than the fair scheduling used by TCP. So, just to wrap up,
the role of short messages in AI appears to be increasing. I think I think it's likely that it's going to continue to increase. We'll see over the next year or two if that happens. And I just want
to pose a question to you. You know, as you're running your applications and measuring performance and seeing what the bottlenecks are, ask yourself, is high latency for short messages
affecting your throughput? If the answer is yes, then just know there is a solution available. You should give HOMA a try. You can probably reduce your tail latency by an order of magnitude or
more. And by the way, this is Home is basically my life mission right now. I'm sort of semi-retired from Stanford. The reason I did that is so I can spend 100% of my time hacking on Homa. So I'd be
delighted to work with you and help you if you decide you want to experiment with Homa. If you need help getting started, answer questions, bug fixes, whatever, you know, I'd be happy to work
with you to try and make you successful with it. So if that is interesting, feel free to contact me. My email is on the slide or you can Google me too and find me over the internet. So thanks very
much for listening and hope to hear from some of you. >> [music]