Videos
| Thumb | Title | Channel | Status | Published |
|---|---|---|---|---|
|
GPT-6 Luna First Test – Is OpenAI’s CHEAPEST Model Actually Good?
GPT-6 Luna is OpenAI's cheapest model at $0.10 per million input tokens and $0.50 per million output tokens, and it... |
Bijan Bowen | summarized | 2026-09-28 10:54 |

|
The Secret GPU Kernel Behind DeepSeek V4.1 Flash
DeepSeek V4.1 Flash uses a custom GPU kernel called Deep Select to reduce per-token KV cache to 890 bytes, down from... |
Cloud Codes | summarized | 2026-09-13 09:00 |

|
Deepseek did it again...
DeepSeek V4.1 Flash is a 552B parameter MoE model with only 8B/16B active parameters, matching Opus 5 and GPT 5.6 on... |
Matthew Berman | summarized | 2026-09-11 19:01 |

|
I Analyzed How Anthropic ACTUALLY Prompts Fable 5.1
Anthropic's documentation for Claude Fable 5.1 reveals that the model performs best when given a clear outcome... |
Nate Herk | summarized | 2026-09-02 21:53 |
|
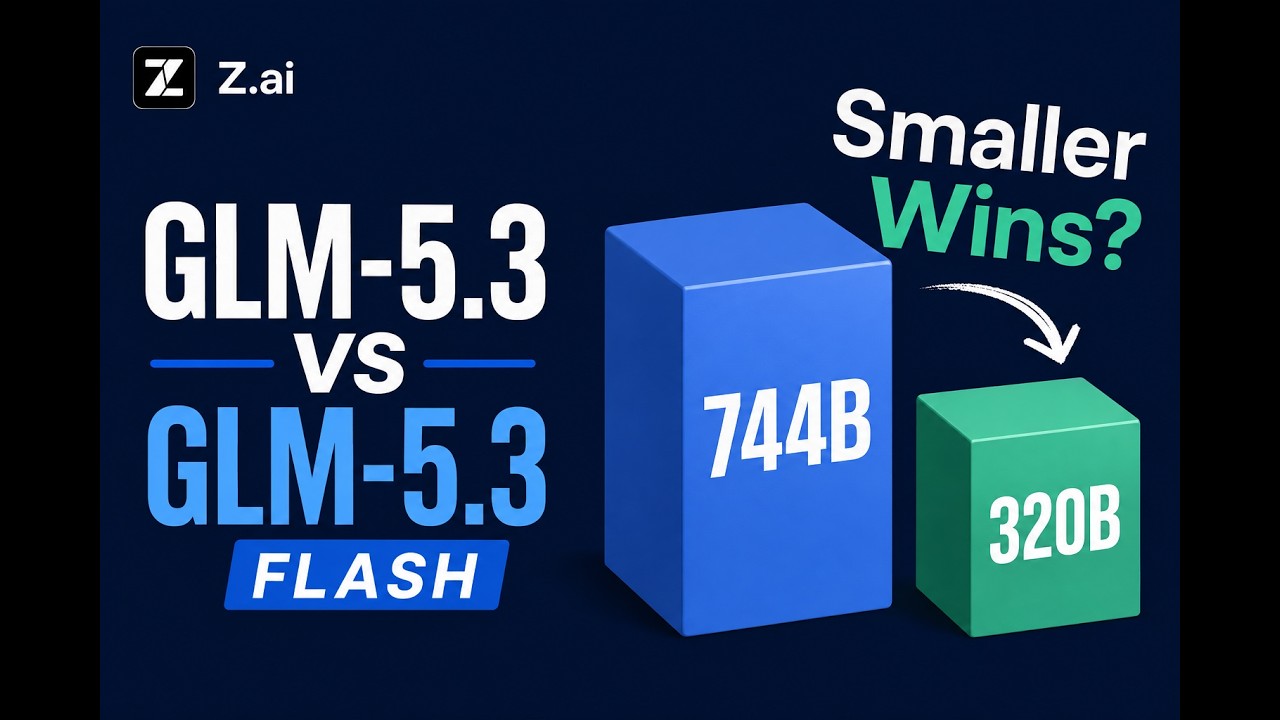
GLM 5.3 Flash vs GLM 5.3: When Cheaper Is the Right Call
GLM 5.3 Flash delivers near-flagship performance at roughly 1/9th the cost of GLM 5.3, but its heavy token usage for... |
Sam Witteveen | summarized | 2026-08-30 15:20 |

|
I Tested Claude Code vs. Codex on Design. It Wasn't Even Close.
In a head-to-head test of eight website builds with identical prompts, Codex consistently outperformed Claude Code... |
Nate Herk | summarized | 2026-08-26 12:38 |

|
Tibo: Ultrafast Mode, The Reset Button, OpenAI vs Anthropic, RSI, and more!
OpenAI's decision to merge ChatGPT and Codex into a single product reflects a conviction that future AI models will... |
Matthew Berman | summarized | 2026-08-24 18:11 |

|
Generative Video at the Speed of Light — Keegan McCallum, uRun
Generative video models are now efficient enough to generate video faster than you can watch it, at a fraction of... |
AI Engineer | summarized | 2026-08-18 16:30 |
|
10 AI Skills: Don't Learn Prompting (Do This Instead)
The gap between agent performance is driven by the harness (the loop around the model), not the model weights alone:... |
Cloud Codes | summarized | 2026-08-05 20:00 |

|
ThinkingCap - The Local Coding Model
Bottle Cap AI's ThinkingCap fine-tune of Qwen 3.6 27B reduces reasoning tokens by ~46% while preserving benchmark... |
Sam Witteveen | summarized | 2026-07-30 13:00 |

|
Kimi K3 explained in 13min..
Kimi K3 nearly matches Anthropic and OpenAI in benchmarks, but its real impact is through architectural innovations... |
Caleb Writes Code | summarized | 2026-07-21 19:59 |

|
The Desktop Frontier — Ahmad Osman, Osmantic
Local and open-source AI models are rapidly improving in capability density, with newer efficient models... |
AI Engineer | summarized | 2026-07-21 02:28 |
|
The EXACT AI Tool Stack Every Founder Needs (Foolproof)
AI tool stacks can replace traditional company functions, reducing costs by over 99%. The five-layer stack consists... |
AI Founders | summarized | 2026-06-07 17:00 |
Frontier News · by Hyperjump Technology