Videos
| Thumb | Title | Channel | Status | Published |
|---|---|---|---|---|
|
Can you run Strata Local Ai Engine on a SINGLE 12GB GPU?
Strata local AI runs on a single 12GB 3060 and works surprisingly well, averaging about 49 tokens/sec decode once... |
Digital Spaceport | summarized | 2026-10-12 17:10 |

|
AI Apps in a Flash: Ship to GPUs Without Docker — Dean Quiñanola, Runpod
Runpod Flash is a serverless AI deployment platform that eliminates the Docker build-push-execute loop. The CLI... |
AI Engineer | summarized | 2026-10-11 18:00 |

|
Agents That Own Their Inference — Du'an Lightfoot & Khaja Omer, Akamai Technologies
Owning agent inference on a dedicated GPU is cheaper and faster than renting API intelligence for steady workloads:... |
AI Engineer | summarized | 2026-10-11 14:00 |

|
RTX 5090 Is Ending? Don’t Panic-Buy a GPU for Local AI
Memory capacity and bandwidth, not GPU model numbers, decide what a card can run for local AI. The RTX 5090's 32 GB... |
Cloud Codes | summarized | 2026-10-11 12:00 |

|
GPU Died. Training Didn't: Self-Healing Training at Scale — Crusoe
Crusoe's autoclusters system makes GPU failures a non-event for large-scale training: a critical hardware error... |
AI Engineer | summarized | 2026-10-03 21:00 |

|
Which GPU Clouds Are Actually Good? | ClusterMAX 3.0
Semi Analysis’s ClusterMAX 3.0 reveals that most NeoClouds have terrible cybersecurity, with issues like outdated... |
Latent Space | summarized | 2026-10-02 05:22 |

|
Qwen3.8-Flash-Next at 45 Tokens/sec on a 12GB GPU?
Strata, an Engine 1 developer's inference engine for Qwen-3 8B Flash Next, claims 44.8 tokens/second on a 12GB RTX... |
Cloud Codes | summarized | 2026-09-28 12:00 |

|
Run Your Own AI Coder on a 6GB GPU (No Subscription)
On a 6GB GPU, the deciding factor for local coding models is not the download size but the memory left over after... |
Cloud Codes | summarized | 2026-09-20 05:30 |
|
What If You Run a Database Query on a GPU?
A GPU running a cold database query loses to a CPU because 97% of the time is spent moving data, not computing.... |
Cloud Codes | summarized | 2026-09-16 09:00 |
|
The Best Local AI GPUs to Buy Right Now (Buyer's Guide)
The RTX 5090 carries a $3,400 premium over MSRP due to FOMO and export demand, making it the worst value for local... |
Digital Spaceport | summarized | 2026-09-16 03:15 |

|
They Say AI Is for the Rich. Here's the Way Out.
A $200/month AI subscription costs 2.4% of US GDP per capita but 89% of India's, making affordability deeply unequal... |
Cloud Codes | summarized | 2026-09-09 09:00 |

|
Everyone Got NVIDIA PAIR Wrong
NVIDIA PAIR is not a GPU pooling tool that combines memory across machines. It is a request-level load balancer that... |
Cloud Codes | summarized | 2026-09-06 10:09 |

|
Infra behind Krea 2: How to train and serve at scale — Gabriel Jorge Menezes, Krea.ai
Krea.ai trained K2, a diffusion transformer from scratch on thousands of GPUs, and built infrastructure to... |
AI Engineer | summarized | 2026-08-18 17:00 |

|
Mojo 1.0 Is Here: The CUDA Rival Goes Stable
Modular shipped Mojo 1.0 with a stability promise, but skipped publishing any new performance numbers—a telling... |
Cloud Codes | summarized | 2026-08-12 20:00 |
|
CUDA vs ROCm: Why ROCm Sucks at Every Step
AMD's MI355X GPU matches or beats Nvidia's B200 on paper but loses by a third in benchmarks due to software issues... |
Cloud Codes | summarized | 2026-08-05 17:49 |

|
The Inference Frontier: 10x Faster Models to Self-Optimizing AI — Philip Kiely & Ali Taha, Baseten
Inference engineering for large language models involves a stack of optimizations including KV cache-aware routing,... |
Latent Space | summarized | 2026-08-03 21:35 |
|
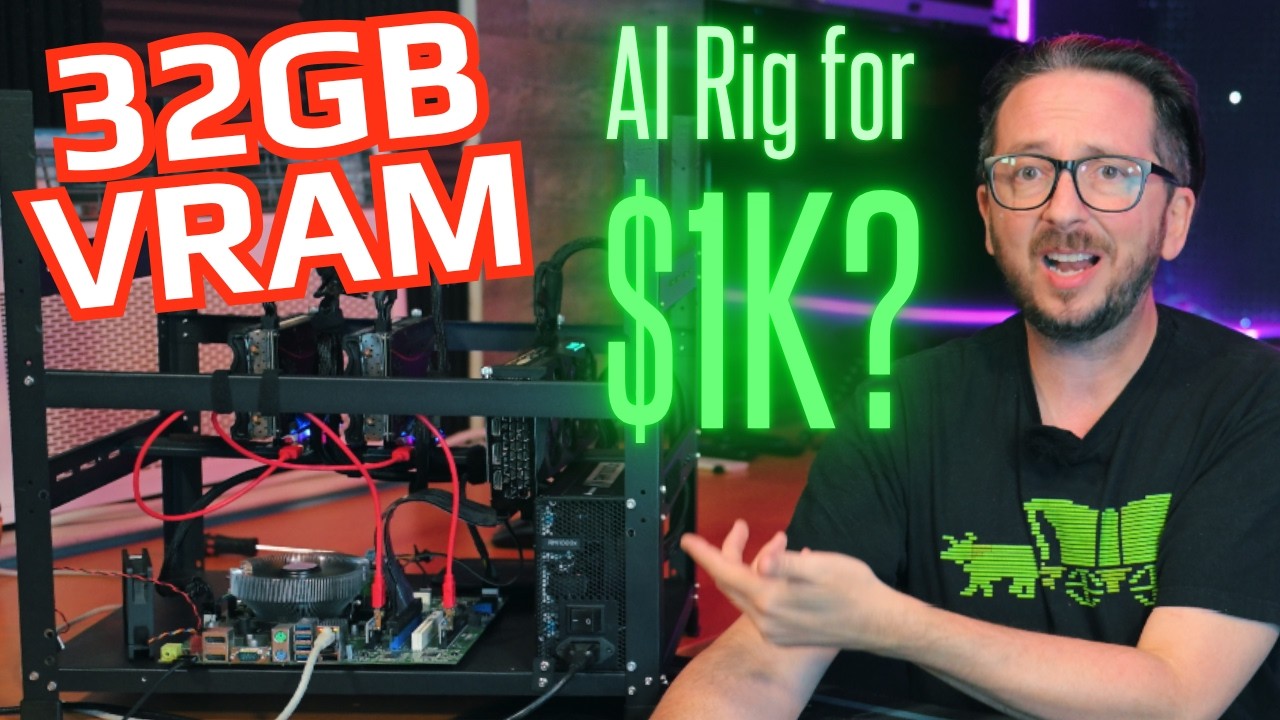
$1000 Budget Local Ai Rig
A Dell Optiplex motherboard can be transplanted into a custom frame to create a budget local AI rig for under $1000,... |
Digital Spaceport | summarized | 2026-07-06 14:00 |
Frontier News · by Hyperjump Technology