Videos
5 total
| Thumb | Title | Channel | Status | Published |
|---|---|---|---|---|
|
AI Models Talk Better Without Words?
C2C (cache-to-cache) passes a sharer model's KV cache directly to a receiver model via a trained fuser, skipping... |
Cloud Codes | summarized | 2026-10-07 15:15 |
|
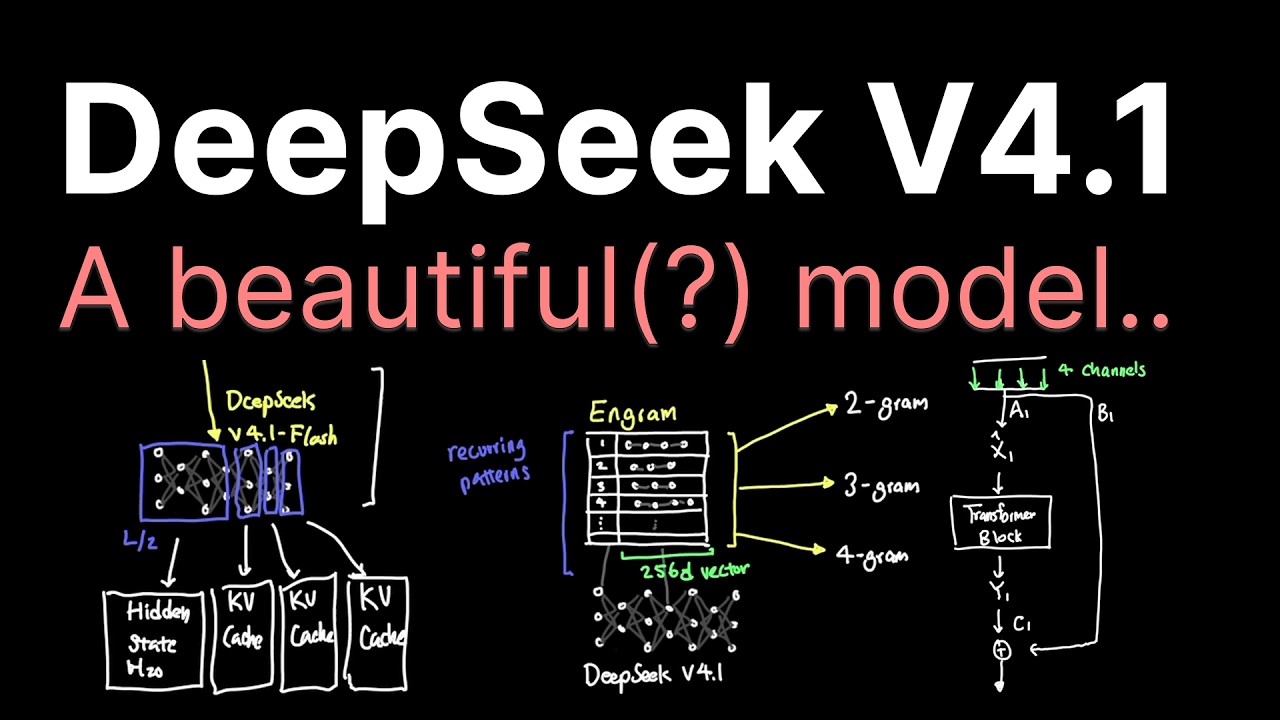
DeepSeek V4.1 Flash made encoders cool..
DeepSeek V4.1 Flash uses a Causal Encoder-Decoder architecture that halves prefill compute by processing input... |
Caleb Writes Code | summarized | 2026-09-16 20:29 |

|
The Secret GPU Kernel Behind DeepSeek V4.1 Flash
DeepSeek V4.1 Flash uses a custom GPU kernel called Deep Select to reduce per-token KV cache to 890 bytes, down from... |
Cloud Codes | summarized | 2026-09-13 09:00 |

|
KV Cache-Aware Routing and P/D Disaggregation on Kubernetes — Yuchen Fama & Ashish Kamra, Red Hat
LLMD's KV cache-aware routing and prefill-decode disaggregation address the chaotic inference patterns of agentic... |
AI Engineer | summarized | 2026-08-27 14:00 |
|
NVIDIA Just Made AI Memory Transferable Between Models (KV Cache Transfer)
NVIDIA's research shows that KV cache, previously thought model-specific, can be transferred between models using a... |
Cloud Codes | summarized | 2026-08-09 16:00 |
Frontier News · by Hyperjump Technology