Videos
| Thumb | Title | Channel | Status | Published |
|---|---|---|---|---|

|
NVIDIA Wants to Buy America’s Open AI Hope #shorts
Nvidia's reported talks to buy or invest in Reflection AI are part of a pattern of deal structures that mix... |
Cloud Codes | summarized | 2026-10-12 10:24 |

|
RTX 5090 Is Ending? Don’t Panic-Buy a GPU for Local AI
Memory capacity and bandwidth, not GPU model numbers, decide what a card can run for local AI. The RTX 5090's 32 GB... |
Cloud Codes | summarized | 2026-10-11 12:00 |
|
This 6k AMD PC DESTROYS NVIDIA's DGX Spark?!
Loose Box's $5,999 AMD-based system claims 3.4x faster inference on Deepseek V4 Flash than Nvidia's DGX Spark, but... |
Cloud Codes | summarized | 2026-10-10 12:00 |

|
Don't Buy the DGX Spark 64GB (Buy This Instead)
The 64GB DGX Spark at $4,999 is a poor value compared to the Mac Mini M5 Pro, which offers faster memory and costs... |
Cloud Codes | summarized | 2026-10-06 10:00 |

|
NVIDIA’s Plan to Stop AI Agent Attacks
Nvidia's Open Agent Safety Platform is a layered answer to AI agents overriding their own safety instructions. Open... |
Cloud Codes | summarized | 2026-10-03 18:30 |

|
Qwen 3.8 27B Starts Answering 1.78× Faster With One Trick
An untouched one-bit Qwen 3.8 27B jumps from 29% to 61.5% on MMLU Pro and cuts time-to-first-token from 12.27 to... |
Cloud Codes | summarized | 2026-10-03 10:30 |
|
Is NVIDIA Insane? $4,999 DGX Spark 64GB
NVIDIA is releasing a 64 GB DGX Spark at $4,999, halving the VRAM of the original 128 GB model while keeping the... |
Digital Spaceport | summarized | 2026-10-02 18:45 |
|
DeepSeek + Huawei = END of Nvidia?!
Switching matrix operations from Nvidia GPUs to Huawei's Ascend requires far more than a chip swap — the data... |
Cloud Codes | summarized | 2026-10-02 18:30 |

|
Did Alibaba Just Solve China's AI Chip Problem?
Alibaba's Zhenru 900 beats Nvidia's H200 on paper in exactly two published specs, 216GB memory versus 141GB and a... |
Cloud Codes | summarized | 2026-10-01 19:30 |
|
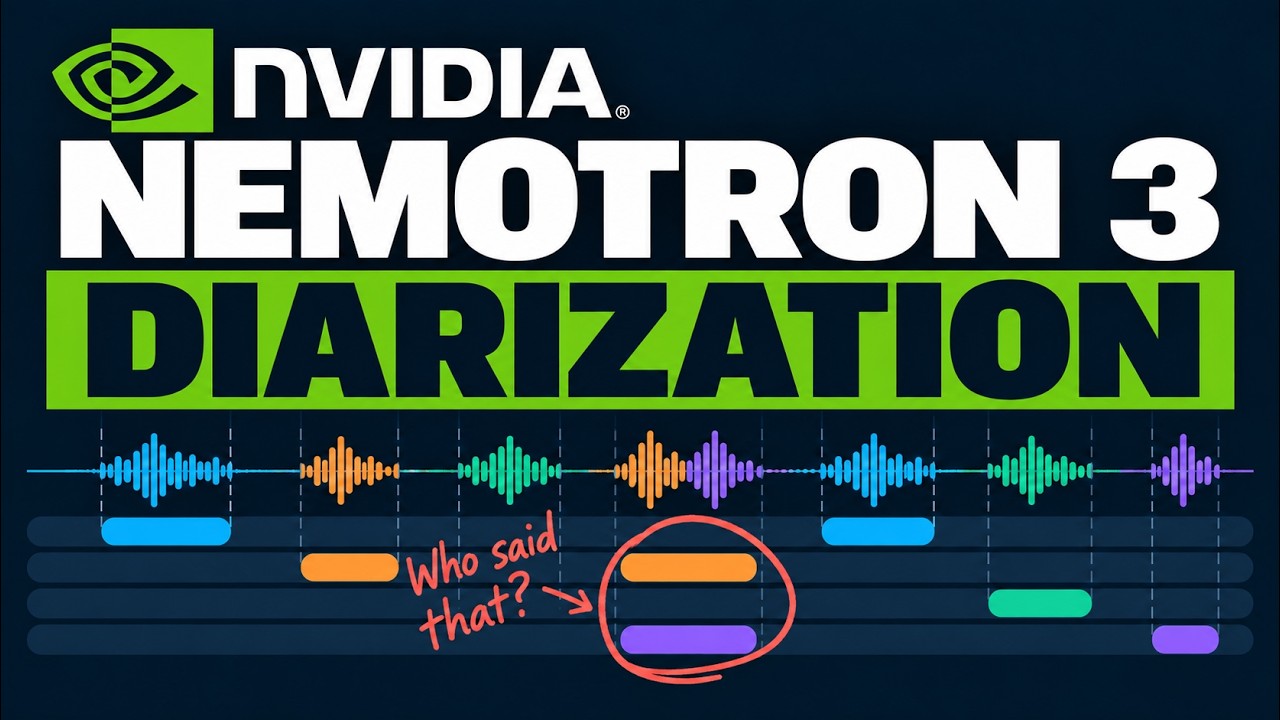
Nemotron 3 Diarization - Who Said That?
Nvidia's Nemotron 3 diarization model (roughly 100 million parameters, 4 GB GPU minimum) handles up to eight... |
Sam Witteveen | summarized | 2026-09-23 15:36 |

|
Your Agreements Are a Database You Can't Query — Hiral Shah, Docusign & Sean Sodha, NVIDIA
Docusign and NVIDIA built a purpose-built small VLM (Neotron Parse, ~850M parameters) that extracts complex tables... |
AI Engineer | summarized | 2026-09-16 15:30 |
|
The Best Local AI GPUs to Buy Right Now (Buyer's Guide)
The RTX 5090 carries a $3,400 premium over MSRP due to FOMO and export demand, making it the worst value for local... |
Digital Spaceport | summarized | 2026-09-16 03:15 |
|
NVIDIA Doubles Down on Local AI With PAIR
Nvidia's open-source PAIR router allows agents to distribute inference across multiple local machines, each handling... |
Sam Witteveen | summarized | 2026-09-06 14:45 |

|
Everyone Got NVIDIA PAIR Wrong
NVIDIA PAIR is not a GPU pooling tool that combines memory across machines. It is a request-level load balancer that... |
Cloud Codes | summarized | 2026-09-06 10:09 |
|
Did China Really Build an AI That Writes CUDA Better Than Humans?
ByteDance and Tsinghua's CUDA Agent beats PyTorch's compiler on 97% of 250 benchmark tasks, but the claim that it... |
Cloud Codes | summarized | 2026-09-03 19:30 |

|
This makes Claude Free Forever
A GitHub repo with over 50,000 stars aggregates free API keys from 50 providers, giving Claude Code users 1.3... |
Jack Roberts | summarized | 2026-09-01 20:27 |

|
Full Analysis: OpenAI Jalapeño chip..
OpenAI's custom inference chip, Jalapeno, designed with Broadcom in 13 months, shows preliminary benchmarks that... |
Caleb Writes Code | summarized | 2026-08-27 22:56 |

|
Mac Studio M5 Ultra is a DGX Spark Killer for Local AI
Apple's new Mac Studio M5 Ultra (512GB, 1.2TB/s) is the first Apple product the speaker considers a genuine DGX... |
Digital Spaceport | summarized | 2026-08-25 23:17 |
|
NVIDIA Spending $6B on an Open-Weight Model (But Why?)
NVIDIA paid $6 billion for a non-exclusive license to Poolside's model factory and 109 of its employees, not for the... |
Cloud Codes | summarized | 2026-08-25 19:30 |

|
New Local AI Engine Everyone Will Be Using in 2027 ? (FreeToken)
FreeToken's routing-aware expert caching cuts cache misses to 16% versus 62% for llama.cpp's static split,... |
Cloud Codes | summarized | 2026-08-22 19:00 |

|
NVIDIA NOOA vs LangChain: Half the Tokens, Higher Score
Nvidia's NOOA (Object-Oriented Agents) framework argues that most agent framework machinery—prompt templates, tool... |
Cloud Codes | summarized | 2026-08-20 09:00 |

|
Nemotron 3.5 Lightning Is NOT a Transformer (Mamba + MoE Explained)
Nvidia's Nemotron 3.5 Lightning is 88% not a transformer — it's a hybrid of Mamba state-space layers and... |
Cloud Codes | summarized | 2026-08-13 09:00 |
|
Nemotron 3.5 Lightning First Test – NVIDIA’s NEWEST Open Model!
Nvidia dropped Nemotron 3.5 Lightning, a 30-billion-parameter mixture-of-experts model with only 3 billion active,... |
Bijan Bowen | summarized | 2026-08-12 13:48 |

|
Nemotron Lightning - NVIDIA's Super Fast Agent MoE
NVIDIA quietly released Nemotron Lightning, a small open-weights MoE model (30B total, 3B active) built specifically... |
Sam Witteveen | summarized | 2026-08-11 13:30 |

|
Switchyard NVIDIA's Local Agent Router
NVIDIA's Switchboard is an open-source routing library that sits between your agent and its models, deciding... |
Sam Witteveen | summarized | 2026-08-11 13:00 |
|
NVIDIA Just Made AI Memory Transferable Between Models (KV Cache Transfer)
NVIDIA's research shows that KV cache, previously thought model-specific, can be transferred between models using a... |
Cloud Codes | summarized | 2026-08-09 16:00 |

|
The State of Model Routing — NVIDIA, Cognition, OpenRouter
Model routing is an emerging field where systems intelligently delegate tasks between large frontier models and... |
AI Engineer | summarized | 2026-08-06 17:07 |
|
CUDA vs ROCm: Why ROCm Sucks at Every Step
AMD's MI355X GPU matches or beats Nvidia's B200 on paper but loses by a third in benchmarks due to software issues... |
Cloud Codes | summarized | 2026-08-05 17:49 |

|
This letter could change EVERYTHING
A debate is intensifying between proponents of open-source AI, led by Nvidia's Jensen Huang, and closed-source... |
Matthew Berman | summarized | 2026-07-29 17:52 |
|
NVIDIA’s Nemotron 3 Is... Awesome?
NVIDIA's Nemotron-3 models come in Nano, Super, and Ultra variants sized for consumer hardware, workstation/server... |
Caleb Writes Code | summarized | 2026-06-11 06:26 |
Frontier News · by Hyperjump Technology