Enjoying this issue?
Get tomorrow's AI & engineering digest in your inbox — hand-picked, summarized, and always spam-free.
TLDR
OpenAI's inference load balancer evolved from a feedback-loop-based P controller to a control plane/data plane architecture that uses a global optimizer to minimize end-to-end latency. The key insight is that routing decisions must balance network distance and engine-side latency, and that a globally optimized routing weight computed asynchronously avoids the oscillations and reasoning difficulties of the previous approach.
Key points
The old routing system used a P controller feedback loop that combined multiple signals but was hard to reason about and caused oscillations.
The new architecture separates control plane and data plane, with the control plane computing routing weights asynchronously.
The optimizer minimizes expected end-to-end latency including both network distance and engine-side latency.
Protection mechanisms include penalties for outlier engines, retry caps to prevent retry storms, and load shedding as a last resort.
The system must respect hard constraints: route all traffic, keep engines within capacity, and keep routing weights non-negative.
Techniques
- proportional control (P controller)
- global optimization for routing
- control plane/data plane separation
- asynchronous routing weight updates
- load shedding
- retry caps
Stop scrolling. Start reading smarter.
Receive the day's most important AI & engineering updates in one concise email. No spam.
Transcript (captions)
Hi everyone, thanks for joining our talk. I'm Lou and this is my colleague Chenu. So we today we're going to talk about the in uh we both work on the inference team at OpenAI and today we
are going to talk about routing IM inference in production specifically how our system evolved from routing based on feedback loops driven by engine signals to a more explicit and a predictable
policy which is still informed by engine signals. However, it's more like the way we use it is different. So uh for the agenda today we're going to begin by introducing the inference
load balancer what it is what it does and how it has evolved and then Chenu will walk us through the newer control plane and data plane driven architecture uh what are the responsibilities of each
and followed by a concrete case study of how we reduce the global network overhead and in the end I return to discuss the protection mechanisms that help keep the system stable and
production level stress. So to begin with what is the inference load balancer and where it sit? So this is a very high level diagram of the system we are talking about. On the left
hand side are the front end clusters. Those are the GPU cluster. Sorry, those are the CPU clusters that act as gateways into our system and they receive user requests then prepare them
into the inference request that can be processed by the inference engines and on the right hand side are the engine clusters uh which are usually GPU clusters and each hosting multiple
inference engines. So that's why we they got the name of engine clusters and as you may already heard nowadays GPUs are pretty popular and expensive. So um sitting in the middle it is the IRB or
inference load balancer. It actually runs on the front end clusters but is also a bridge into our inference stack. It has two main responsibilities select an engine and proxing the request. For
this talk, we are going to focus on the engine selection part. So in some ways, IRB resembles a very traditional load balancer because a request usually targets a model and a model is backed by
multiple engines. They may live on different clusters in different regions or even across the continents because that gives us a good resiliency towards localized degradation or cluster
failures. However, the inference uh stack or the uniqueness of the inference introduces a lot of nuances like uh it has to consider a bunch of signals reported in real time like the
well-known time to first token TTF time between output tokens also known as token throughput or time between tokens and other hairness and utilization signals. Besides there's a important
concept of a KV cache which is also well known but for example when the conversation already has a lot of the useful context cached in one engine sending the follow-up turns of the same
conversation back to the same engine will avoid recomputation improve efficiency and uh reduce latency. So the combination of performance reliability locality cach awareness is what makes it
such an interesting problem. Uh so how we attempted in the problem? Let's take a look at the early days. And to be honest, early days in in this industry sounds a lot more historic than it
really is. And the routing process at that time began with a fear of like each request may not be served by all the engines because of uh constraints such as capabilities or due uh restrictions
due to compute or data residency. And among the remaining engines, IRB used a weighted consistent hashing to select the best destination engine for a request or of for certain user. Then the
important question becomes where are the WS come from. So they were generated by a periodic feedback loop. The inference engines as mentioned earlier uh reports all kind of the signals we care about
and the controller will periodically smooth out those signals and compute a performance score. The performance score then will be compared against the fleet average. Then the weight will be
adjusted basically for each engine. is weight goes up if the performance is better or it goes down when the performance is worse than the fleet average and this generated weight will
impact the routing and then it's basically a uh control loop um conceptually it is very similar to the P controller and no this P controller will not help you care a Linux process but
instead it's a classic control theory technique that continuously steering the system towards its desired date and we just borrowed this important concept the proportional part of it and uh applied
into our uh our load balancer. So it has a lot of nice properties. For example, it could combine the useful signals we care about into the single routing decision and because of the it adapt to
the observed performance as what we mentioned earlier there's a lot of constraints and those constraints might have the some engines basier because they can serve more requests more kind
of request than the remaining but those basier signal will be fit into the next loop and resulting in the less constraint less constraint request can go to more of those kind of engines. So
basically they self balanced out and to some extent this just means we don't need to do a lot of manual intervention and it just works. However that kind of adaptability comes with big trade-offs
because of the same reasons that it combined so many signals. It's also very hard to reason about a particular routing decision or like why search engine get a higher weight than we
expect. And every time we want to fine-tune towards some aspect, it's all almost impossible to not impacting something else. And the load is not always very well
very evenly distributed because uh sometimes a model is served by engines on different GPU skills and they have different characteristics. Then the problem becomes a lot more trickier and
the feedback loop sometimes creates bad oscillations because when you shift an engine away some traffic the engine turns a bit cooler and this signal get fit to the
controller. The controller now thinks that hey this engine can take a lot more traffic. then the some traffic going to be shifted back and forth between a few engines and disrupting the KV cache
utilization. So all those limitations motivated us to rethink about the architecture and uh see if we have new ways to address the problem. So I'm going to hand over to Chenu to uh deep
dive into the new architecture we tried out. >> Yeah, thank you L. So I'm going to talk about the architecture of the load balancer and how do we reduce the
overall overhead with our routing algorithm. The load balancer answers one question uh for each request from a CPU cluster which engine should serve it. One most
naive baseline might be round robin which send requests across engines evenly. But if you think a little bit more that doesn't make sense because engines are not homogeneous they can
have different hardware and capacity different health and also different distance from CPU cluster also run could break cache locality c related requests that could reuse the
same engine cache might be sent to different engines. A probably better solution might be for each CPU cluster it choose the best engine from its own local view. But
that's not enough either. Think about one extreme case. Multiple CPU cluster route traffic to the same engines independently which could overload that engine while leave other engines
underutilized. So what we need is a globally optimized solution, a control plane that has a global view for all the CPU cluster and GPU engines and could compute a globally
optimized routing answers and the data plane can make a routing decision quickly based on the answer proved from the control plane. Now let's look inside the control plane
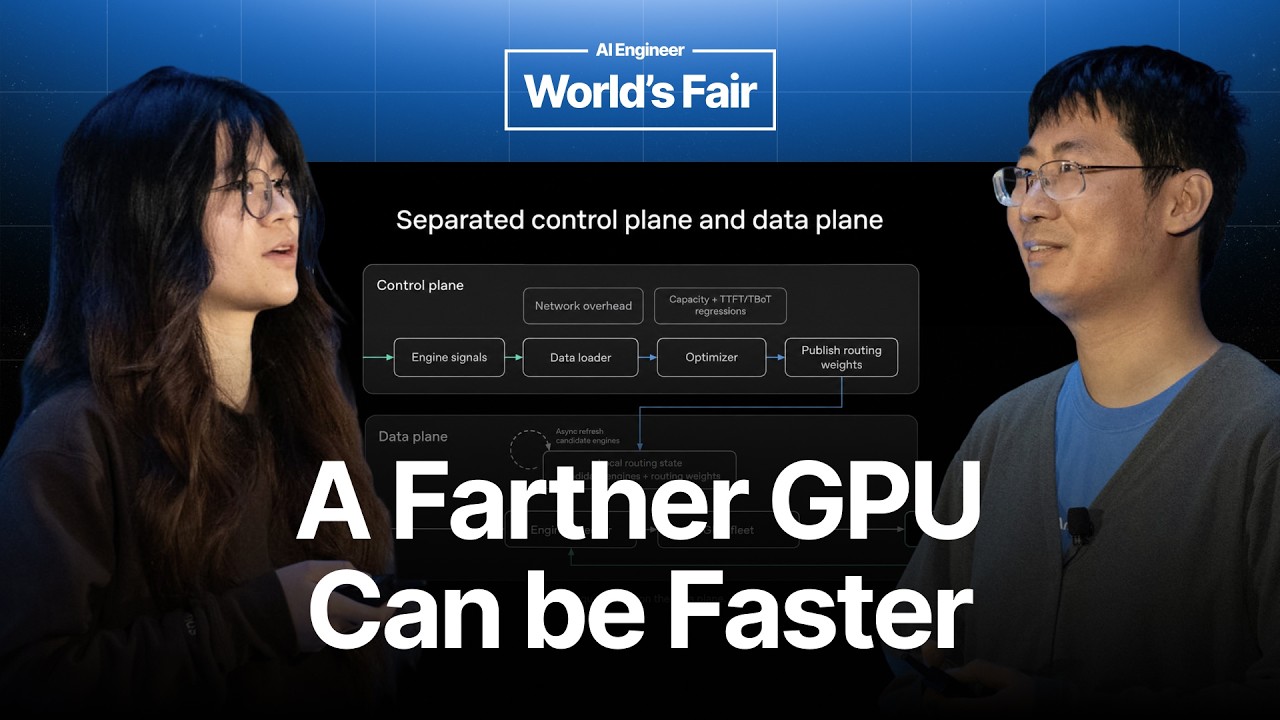
and data plane. In the data plane there is an engine selector which select engine for each request. It read the local routing state which includes the candidate engines and the routing
weights for each candidate engines. Both of them are refreshed asynchronously in the background. So we don't need to ask the control plane before we make a routing decision for each request. Also
the data plane collects realtime engine signal such as number of ready replica engine house etc to surface fast local guard draw in the control plane. The data loader
combines those live engine signals and never overhead. And with offline regressions of capacity, TTFT and TBOT, the optimizer could turn those data into routing weights and the control plane
will publish the routing weight for each data plane to pull. In this way, no request need to wait on the data plane. The control plane continuously compute the next globally optimized routing way
snapshot while the data plane make a routing decision based on the latest snapshot already installed locally. In summary, there are three important paths through the system. The first path
is the inference request path. The request arrive to the CPU cluster and the data plane inside that CPU cluster will select engine for that request based on the local routing state and
forward the request to the selected engines. The second pass is the engine signal pass. The system continuously collects real-time engine signal such as TTFT,
TBOT, number of radio replica and engine house etc. Boost planes need those real-time engine signals. The control plane need them to compute a globally optimized routing way while the data
plane need them to serve as fast local. And the third path is the routing way pass. The control plane compute and publish the routing way and the data plane pull the updates to its local
cache. So only the first pass is synchronous but it's fast and only local inside the data plane of the CPU cluster. The other two loops are asynchronous loop and they
are to improve future routing decision. So that's pretty much of the architecture part. But that still leaves one question. How do we compute those routing weights?
But before answer that question, let's answer another question first. Why not just send a request to the nearest engine? That's because the traffic demand and
GPU capacity are not geographically balanced. For example, in region one, CPU cluster A send 90 RPS and the nearby engine A can serve 100 RPS. So in this case
nearest only is fine while in region two CPU cluster B send 120 RPS and the nearby engine B could only serve 100 RPS. So in this case if we insist on keeping everything local the extra 20
RPS need to wait on an overloaded engine B. While in region three we are only using 40 RPS of an 80 RPS engine C. That still leaves 40 RPS spare. So if we send the extra 20 RPS from cluster B to
engine C, that will add network distance. But it could also avoid a probably much larger engine side waiting time. So in this case, a further engine might be
faster end to end. That's why we need something better than the nearest only routing. Now let's open the black box of the optimizer.
The optimizer accepts four types of input. The request from each CPU cluster, the network latency to each engine, the available engine capacity and health and also the TTFT, TBOT
latency profiles that tell us how's the engine side latency change as the low increases. And with those input the optimizer turn the input to the output routing weights.
The routing way say for each CPU cluster what fraction of its traffic should go to each GPU engine. And the optimization goal is straightforward is to minimize the
expected end to end latency across all routed traffic. The important part is that the end to end latency includes both the network distance and the engine side latency. That means a nearby engine
might be attractive when it still has room to serve traffic while a further engine might be better if all the nearby engines are close to full. And the optimizer also need to respect
several hard constraints. First it need to route all the traffic demand. Second it need to ensure all the engines stay within the effected capacity. Third it need to keep the routing weights non-
negative. With this the controller control plane get the routing way from the optimizer and publish them and the data plane pull them and use them to make a globally
optimized routing decision. And that's pretty much of my part and Lou will continue to talk about the protection mechanisms in the system. Thanks Chenu. So as AI engineers we all
kind of know that production in many cases are not behaving in the most ideal case. So clusters can fail, GPUs or individual nodes can degrade degree and networking can just get to all kind of
mysterious issues. So how do we keep our production system uh heresy as much as possible under the heavy load? The first thing we have is the penalties. Basically when an engine is an outlier,
we detect the try to reduce the routing weight to that engine. In that way, we give it a chance to either recover by themselves if there's a uh if it's some transient issue or we can have a human
intervented out or replace the faulty hardware. And secondly, the retries which is a very common technique used to mitigate a problems. However, during some cases, it's actually could make
them even worse like when the system is very close to like a tip over or very heavy utilized retries, we are send more load and this more load we are cause more failure and cause more retries
which is infamous retry storm. So we incre implemented caps or budget to constant retries into a acceptable region and this is actually even need to be dynamic because in the happy time or
in the normal time we can tolerate a lot more retries than when the system are heavily utilized. And finally we have the load shedding which is our last result when the production capac uh
capacity couldn't meet the increasing amount of inference demands. So we instead try to have all the system fail. We basically proactively load shed a portion of the traffic to have the
system degraded gracefully. So that pretty much concludes our talk today and uh thanks for joining us. Uh both of us will be around in our uh booth area this afternoon. So if you have further
questions, feel free to walk uh to the area and and chat with us. Thank you. [applause]