Videos
| Thumb | Title | Channel | Status | Published |
|---|---|---|---|---|
|
Can you run Strata Local Ai Engine on a SINGLE 12GB GPU?
Strata local AI runs on a single 12GB 3060 and works surprisingly well, averaging about 49 tokens/sec decode once... |
Digital Spaceport | summarized | 2026-10-12 17:10 |
|
Is Learning to Build Software Still Worth It with AI? (My Honest Take)
Learning to build software is still worth it, but the focus shifts from writing code to 'intent engineering' –... |
Cole Medin | summarized | 2026-10-12 15:32 |

|
AAIF Reading Group: Measuring Agent Policy Compliance
The best LLMs only follow complex enterprise policy instructions 36.2% of the time under strict grading, according... |
MLOps.community | summarized | 2026-10-12 15:14 |

|
How Secrets Leak Through AI Agents (and How to Stop It) — Venice AI
Venice AI's approach to privacy in AI agents centers on keeping secrets out of the LLM reasoning layer by tying... |
AI Engineer | summarized | 2026-10-11 16:30 |

|
The Data Context Layer for Agents — Yoni Michael & Brandon Callender, Typedef
Agents fail at data tasks not because they can't write SQL — they fail because they lack a persistent understanding... |
AI Engineer | summarized | 2026-10-11 12:30 |
|
RAG Needs a Map: Using GraphRAG to Retrieve Connected Context — Nyah Macklin, Neo4j
GraphRAG is not a replacement for vector search but an additive layer that lets an agent hop between nodes through... |
AI Engineer | summarized | 2026-10-11 10:30 |

|
Latency Is a Budget. Humanlike Is the Goal. — Jesse Hall, LiveKit
Voice agents fail because the industry optimizes speed instead of behavior, argues Hall: latency is a fixed budget... |
AI Engineer | summarized | 2026-10-11 01:30 |
|
AI Agents Don't Read Your Policy Docs. They Hit Your APIs — Gravitee
AI agents don't read policy documents — they execute API calls. Governance must be enforced at the infrastructure... |
AI Engineer | summarized | 2026-10-10 21:00 |
|
Why Your Company Needs a Context Graph (and How to Build It) — Gil Feig, Merge
Live API calls (MCP) alone cannot handle semantic queries across large datasets; a context graph with synced data,... |
AI Engineer | summarized | 2026-10-09 23:30 |

|
The Smartest People Aren't Prompting Claude. They're Harness Engineering
The video argues that the most effective AI builders focus on 'harness engineering' — building wrappers around... |
Austin Marchese | summarized | 2026-10-09 14:45 |
|
AI Models Talk Better Without Words?
C2C (cache-to-cache) passes a sharer model's KV cache directly to a receiver model via a trained fuser, skipping... |
Cloud Codes | summarized | 2026-10-07 15:15 |
|
They Changed One Equation. 2-Bit AI Got Smarter.
A single loss change, swapping MSE for RMSSE in Omniquant, recovers about 63% of the accuracy gap when quantizing a... |
Cloud Codes | summarized | 2026-10-07 06:04 |
|
Run a 300B AI Model on a 128GB Mini PC (No NVIDIA Needed)
A 300B parameter model can run on a 128GB mini PC using aggressive quantization to ~2-3 bits per weight, sparse... |
Cloud Codes | summarized | 2026-10-06 19:15 |

|
They Switched to 16 DGX Sparks (Running 2.8T AI at Home)
A builder is running Kimi K2, a 2.8 trillion parameter model, on 16 Nvidia DGX Spark boxes at about 21 tokens per... |
Cloud Codes | summarized | 2026-10-06 15:36 |

|
Research to Reality with Google DeepMind — Paige Bailey, Google DeepMind
Gemma 4 is Google DeepMind's latest open model family, released under Apache 2.0, with sizes from 2B to 31B... |
AI Engineer | summarized | 2026-10-05 21:00 |
|
I Built Another Andrej Karpathy Using Claude
A Claude agent that teaches like Andrej Karpathy can be built by crawling his public content, compiling it into a... |
Nate Herk | summarized | 2026-10-05 12:43 |
|
Meta Just Fixed AI's Biggest Flaw?! (CLM's)
Context Language Models (CLMs) give the model control over its own context, allowing it to delete, edit, and... |
Cloud Codes | summarized | 2026-10-04 10:00 |

|
The Free Fix That Doubled AI Speed on Old M1 Macs
A community port of Splash Inco's engine roughly doubles inference speed on 2021 M1 Max Macs for the Quinn 3.8 27B... |
Cloud Codes | summarized | 2026-10-02 10:00 |
|
The Caveman Prompting Challenge
The 'latent shopper problem' is the key challenge for enterprise AI: users often don't know what they're looking... |
MLOps.community | summarized | 2026-10-01 14:00 |
|
Claude Sonnet 5.5 Is INSANE – Seriously, This Model Is Ridiculous!
Claude Sonnet 5.5 absolutely demolished GPT-6 Soul in the presenter's visual task tests, including a GTA clone and a... |
Bijan Bowen | summarized | 2026-09-28 23:28 |

|
How We Built an Agent That Improves Itself — Zubin Aysola, Weights & Biases
Weights & Biases' Arya agent uses its own production traces and offline evaluations to generate new tasks and prompt... |
AI Engineer | summarized | 2026-09-26 16:00 |

|
Anthropic Revealed Their Secret Guide to Mastering Opus 5.5
Anthropic's official Opus 5.5 prompt guide is built around one practical shift: the model now defaults to medium... |
Brock Mesarich | AI for Non Techies | summarized | 2026-09-26 14:22 |
|
Xiaomi Shrunk 12GB of AI Memory to 2.7GB (MiMo-V3)
MiMo-V3 introduces two techniques—KV bridging and KV reuse—that shrink a million-token KV cache from 12.09 GB to... |
Cloud Codes | summarized | 2026-09-26 12:00 |
|
Teaching LLMs to Speak Spotify — Yves Raimond & Jacqueline Wood, Spotify
Spotify's Large Taste Model, used daily by a quarter of US premium subscribers, shifts personalization from ranking... |
AI Engineer | summarized | 2026-09-25 14:30 |

|
Why LLM Recommenders Will Be AI's Biggest Consumer App — Devansh Tandon, Meta
Recommendation systems follow the same power-law scaling curves as LLMs. Meta's research lead argues the field is... |
AI Engineer | summarized | 2026-09-25 14:00 |

|
Distill the LLM, Don't Serve It: Search & Personalization at DoorDash — Raghav Saboo, DoorDash
DoorDash treats LLMs as offline reasoning engines for search and personalization rather than serving them online.... |
AI Engineer | summarized | 2026-09-25 13:30 |

|
GPT-6 Luna Might Be the Best Deal in AI
GPT-6 Luna is OpenAI's new cost-performance workhorse: 10 cents per million input tokens, 50 cents per million... |
Matthew Berman | summarized | 2026-09-23 20:19 |

|
Claude Opus 5.5 Is INSANE – Hands-On With the BEST Model Yet!
Claude Opus 5.5 is a cheaper, capable successor to Opus 5: Anthropic claims it matches a top-tier model (called... |
Bijan Bowen | summarized | 2026-09-22 22:42 |

|
Anthropic Just Dropped Claude Opus 5.5 (Full Breakdown)
Anthropic's Claude Opus 5.5 matches the performance of Fable 5.1 on most tasks while costing 40-51% less to run and... |
Brock Mesarich | AI for Non Techies | summarized | 2026-09-22 20:45 |
|
Does splitting the prompt cut token use in half?
Splitting a voice agent's prompt into per-step contexts cuts token usage by more than half in production, according... |
MLOps.community | summarized | 2026-09-21 14:39 |

|
10 Wild Things You Can Build With Jev
Jev is a decision-only model from Type Safe that outputs a fixed-choice answer with a confidence score instead of... |
Cloud Codes | summarized | 2026-09-21 12:00 |

|
The Fatal Flaw in Modern AI (Exposed by a 1998 Game)
A 1998 StarCraft: Brood War benchmark called Brood War Bench shows frontier AI models lose badly in real-time... |
Cloud Codes | summarized | 2026-09-21 05:30 |

|
Run Your Own AI Coder on a 6GB GPU (No Subscription)
On a 6GB GPU, the deciding factor for local coding models is not the download size but the memory left over after... |
Cloud Codes | summarized | 2026-09-20 05:30 |
|
Routing LLM Inference in Production: From Engine Signals to Policy — Qianru Lao & Lu Zhang, OpenAI
OpenAI's inference load balancer evolved from a feedback-loop-based P controller to a control plane/data plane... |
AI Engineer | summarized | 2026-09-19 15:30 |
|
This AI Claims a 200× Speedup. Here’s the Catch.
Jev, a system one model from Typesafe, claims up to 200x speedup on decision tasks by selecting from predefined... |
Cloud Codes | summarized | 2026-09-17 09:00 |
|
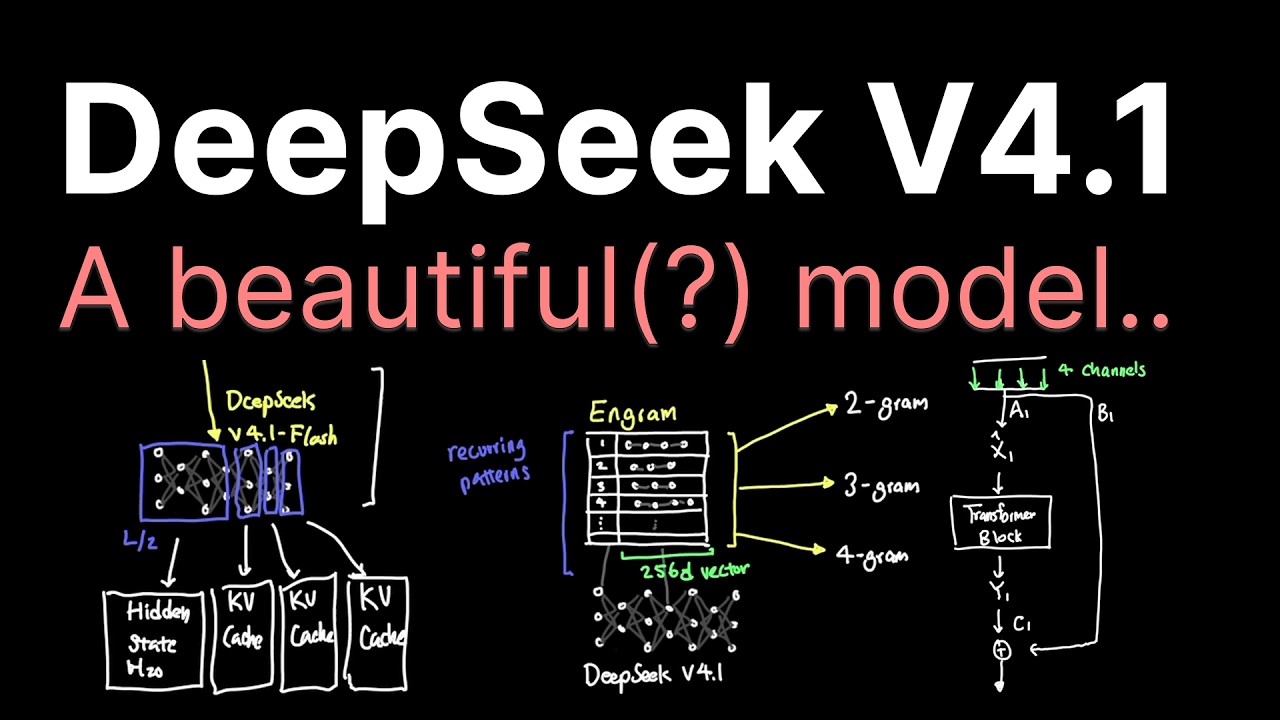
DeepSeek V4.1 Flash made encoders cool..
DeepSeek V4.1 Flash uses a Causal Encoder-Decoder architecture that halves prefill compute by processing input... |
Caleb Writes Code | summarized | 2026-09-16 20:29 |

|
Where RL Will Take Search — Maximilian-David Rumpf, SID.ai
Reinforcement learning can make search agents roughly 20 times faster and about 100 times cheaper than frontier... |
AI Engineer | summarized | 2026-09-16 16:30 |

|
The Search Engine for the Agentic Web — Will Bryk, Exa
Exa is building a search engine designed specifically for AI agents, arguing that AI systems will soon perform a... |
AI Engineer | summarized | 2026-09-16 14:00 |

|
The unreasonable effectiveness of BM25 for agentic search — Jo Kristian Bergum, Hornet.dev
BM25, a 30-year-old lexical scoring function, is making a strong comeback in agentic search because modern LLMs can... |
AI Engineer | summarized | 2026-09-16 13:30 |

|
Realtime Voice Agents with Frontier Intelligence — Bohan Li, EliseAI
EliseAI's cascaded voice agent architecture uses a streaming speculative transcriber (layering fast Flux on accurate... |
AI Engineer | summarized | 2026-09-15 16:00 |

|
The Spatial Harness: Bringing Agents to the Canvas — Max Drake, tldraw
tldraw's spatial harness for agents turns the infinite canvas into a medium where LLMs can understand 2D space, set... |
AI Engineer | summarized | 2026-09-10 14:00 |

|
AI Can't Think Like Human But..
AI models do not think like humans; they lack the abductive reasoning that humans use to invent explanations from... |
Cloud Codes | summarized | 2026-09-09 19:30 |
|
100 Hours Testing GPT-6 Astra vs Fable 5.1. What You Need to Know.
GPT-6 Astra beat Fable 5.1 in 10 of 15 real-world use cases, costing $186 less overall ($327 vs $513) but taking 1... |
Nate Herk | summarized | 2026-09-06 18:05 |
|
Qwen 3.8 27B in 8.4 GB. But Don't Download That One
Two 8.4 GB GGUF files of Qwen 3.8 27B differ by 7.7 points on average benchmarks because one uses a new quantization... |
Cloud Codes | summarized | 2026-09-05 10:29 |
|
Why AI Agents Need Million-Token Context — Thomas Wolf & Olive Song, MiniMax
MiniMax's M3 is the only top-five open-source model that is truly multimodal, packing a 1 million-token context,... |
AI Engineer | summarized | 2026-09-04 13:00 |

|
GPT 6 Astra: The End of Chain-of-Thought?
The looped model Hugging (3.5B parameters, 32 laps) doubles its science score by running more laps, but its silent... |
Cloud Codes | summarized | 2026-09-04 10:08 |
|
GLM 5.3 Flash vs GLM 5.3: When Cheaper Is the Right Call
GLM 5.3 Flash delivers near-flagship performance at roughly 1/9th the cost of GLM 5.3, but its heavy token usage for... |
Sam Witteveen | summarized | 2026-08-30 15:20 |

|
Every Agent Harness Copied a Mistake From JSON
Code has won as the action space for AI agents, but nearly every harness still uses JSON-era timing by waiting for a... |
Cloud Codes | summarized | 2026-08-29 19:30 |

|
Tell the Robot What You Want — Sandhya Subramani, AWS
Strands Agents is an open-source framework from AWS that adds an LLM-powered agent layer to robots, enabling natural... |
AI Engineer | summarized | 2026-08-29 18:30 |
|
Agentic Sites: Building Hyper Personalized Websites — Carlos Sanchez, Adobe
Adobe's Agentic Sites project demonstrates that hyper-personalized web pages can be generated in about 1.1 seconds... |
AI Engineer | summarized | 2026-08-29 17:00 |
Frontier News · by Hyperjump Technology