Videos
| Thumb | Title | Channel | Status | Published |
|---|---|---|---|---|

|
Running Qwen 3.8 Flash Next on a $1000 Local AI Build with Strata
Qwen 3.8 Flash Next, served by the Strata engine on a roughly $1,000 secondhand build, generated a fully interactive... |
Digital Spaceport | summarized | 2026-10-10 02:11 |

|
They Switched to 16 DGX Sparks (Running 2.8T AI at Home)
A builder is running Kimi K2, a 2.8 trillion parameter model, on 16 Nvidia DGX Spark boxes at about 21 tokens per... |
Cloud Codes | summarized | 2026-10-06 15:36 |
|
Is NVIDIA Insane? $4,999 DGX Spark 64GB
NVIDIA is releasing a 64 GB DGX Spark at $4,999, halving the VRAM of the original 128 GB model while keeping the... |
Digital Spaceport | summarized | 2026-10-02 18:45 |
|
OpenAI's Secret Chip Plan: Inside GPT-Synopsys
OpenAI and Synopsys are developing GPT-Synopsys, an AI agent that iteratively modifies chip designs, runs... |
Cloud Codes | summarized | 2026-10-01 21:30 |

|
Local AI GPU Prices are Spiking (Buy Now or Wait?)
Local AI GPU prices are spiking, led by the RTX 5090 up $575 in a week, consistent with a seasonal trend that peaks... |
Digital Spaceport | summarized | 2026-09-27 12:00 |

|
They Say AI Is for the Rich. Here's the Way Out.
A $200/month AI subscription costs 2.4% of US GDP per capita but 89% of India's, making affordability deeply unequal... |
Cloud Codes | summarized | 2026-09-09 09:00 |
|
Before You Buy a Local AI Workstation, Watch This
Local AI workstation capacity specs are misleading: DGX Station's 748 GB is really 252 GB of fast HBM plus 496 GB of... |
Cloud Codes | summarized | 2026-09-08 19:30 |

|
The Inference Frontier: from 100 to 10,000 tokens per second — Sean Lie, Cerebras CTO
Cerebras CS4 runs GPT-4 at over 4,400 tokens per second, and the upcoming CS5 targets 10,000 TPS for medium models... |
Latent Space | summarized | 2026-09-02 17:05 |

|
AI Expert: “Anthropic is lying. Run your local AI instead.”
Anthropic has lied about model quality degradation and used 'safety' to push for regulations that would ban... |
David Ondrej | summarized | 2026-08-27 10:06 |
|
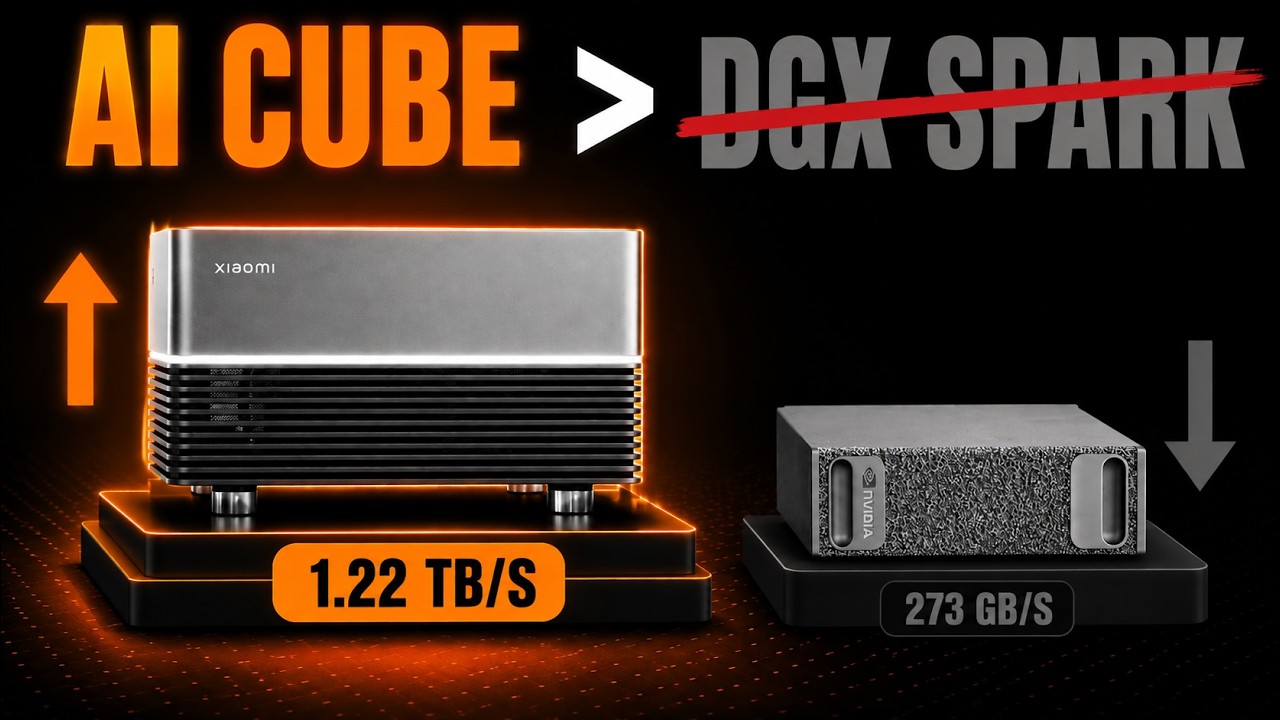
Everyone Got Xiaomi's AI Cube Wrong (4 Errors, One Spec List)
Xiaomi's X-Ring O100 chip achieves 1.22 TB/s memory bandwidth by using wafer-on-wafer hybrid bonding at a 1.4 micron... |
Cloud Codes | summarized | 2026-08-26 09:00 |
|
Run Qwen 3.8 27B Locally: Opus 4.6 max Performance on Your GPU?
Alibaba's Qwen 3.8 27B dense model claims to beat Opus 4.6 on several coding benchmarks while being Apache 2.0... |
Cloud Codes | summarized | 2026-08-15 16:30 |

|
Qwen 3.8 about to drop and this happens... 🔥🥵
Qwen 3.8 (27B model) drops in 20 hours and promises to redefine local AI, but the creator's AC failing at the worst... |
Digital Spaceport | summarized | 2026-08-11 20:51 |

|
The Desktop Frontier — Ahmad Osman, Osmantic
Local and open-source AI models are rapidly improving in capability density, with newer efficient models... |
AI Engineer | summarized | 2026-07-21 02:28 |

|
AI NEWS LIVE
OpenAI unveiled its first hardware device, the Codex Creator Micro keyboard, designed for dictation and thread... |
Matthew Berman | summarized | 2026-07-15 19:56 |
|
Local Ai's Biggest Challenge Yet - Ai News Today
Chinese open-source AI models may face restrictions from the Chinese Ministry of Commerce, threatening the local AI... |
Digital Spaceport | summarized | 2026-07-08 01:41 |

|
OpenClaw in Your Hand: Building a Physical AI Terminal - Lech Kalinowski, Callstack
Lech Kalinowski built a physical AI-native terminal that combines an OLED and e-paper display to serve as both a... |
AI Engineer | summarized | 2026-06-28 21:30 |

|
GPT 5.6 is out… but not for you lol
The US government's ban on the release of GPT 5.6 and Anthropic's Fable model marks an unprecedented moment in AI... |
David Ondrej | summarized | 2026-06-26 21:56 |
Frontier News · by Hyperjump Technology